
Chapter 6 – Affordance
A room within a room
A door behind a door
Touch, where do you lead?
I need something more Daft Punk, Touch (2013)
The Web has made information actionable. For centuries, books and essays have been referring to each other; hypertext has turned those references into links that actually lead us to the other place. In order to scale globally, the Web had to limit the flexibility of links: they point in one direction and can only be created by the publisher of information. Our actions on a webpage remain constrained to those determined by its publisher. As ad-hoc interactions between different online applications become crucial, a linking model that allows a user-centered set of actions seems more appropriate.
Norman’s definition states the term affordance refers to the perceived and actual properties of the thing, primarily those fundamental properties that determine just how the thing could possibly be used
[1].
The world around us is filled with affordances, properties of objects that allow us to perform actions. For instance, a door handle affords opening a door, hence we call it the affordance for opening that door. Similarly, a pen is the affordance that allows us to write any note. However, that same pen can afford stirring a cup of coffee and, with some skill, even opening a bottle. Originally coined by psychologist James Gibson [2], the term gained popularity among technologists through Donald Norman’s book The Design of Everyday Things [1]. Norman wondered why people struggle with everyday appliances, and blamed common frustrations on the lack of properly designed affordances. Especially with the increasing amount of electronic devices that provide tactile capabilities, our intuition of what happens when we touch something (real or virtual) is challenged on a daily basis. This rapid evolution becomes all the more apparent when we find ourselves surpassed by young kids who use technology with a seemingly native ability, faster than we ever will.
Smartphones and tablets have made information even more tangible than it already was.
The virtue of hypertext is that it has transformed information into an affordance. Texts are no longer static and inert, but they can be clicked—on tactile screens even touched—to bring the reader to the next destination. A piece of information is no longer a wall but a door, actionable through a handle. Fielding emphasizes this [3]:
When I say hypertext, I mean the simultaneous presentation of information and controls such that the information becomes the affordance through which the user (or automaton) obtains choices and selects actions. Roy Thomas Fielding
Recall that the Web’s decision for unidirectionality allows global scalability: the Web works because links can break.
When we introduced this definition in Chapter 2, we skimmed over the word affordance
. Together with the hypermedia constraint, we can rephrase the crucial corresponding part as the information must afford the next steps the client wants to take.
However, with the Web’s implementation of hypertext, links can only be added to a piece of information by its publisher. Hence, the information merely affords the actions envisioned by the publisher, which don’t necessarily coincide with those needed by the client. Therefore, on the Web, the information is only the affordance to the extent a publisher can actually predict the controls a client needs. While this might be the case within the closed context of a single application, it is virtually impossible on the open Web.
In particular, it is impossible to afford actions that aren’t possible today, but will be in the future. A few years ago, we couldn’t yet add links to download the tablet version of a movie, even though it was clear that tablets could become popular one day.
For instance, suppose you’re reading a movie review on a webpage. Typically, this page will offer links to pages of cast and crew members and perhaps related movies. Yet, you want to watch the movie in a nearby theater—
Whether REST or RPC are loosely or tightly coupled leads to intense debate; a precise definition of the different facets clears up the discussion [4].
The situation is substantially worse for machine clients that want to engage in a hypermedia-driven interaction. As the previous example shows, an affordance isn’t an enabler: the availability of an action is independent of a control to execute it. However, if the action is not supported through hypermedia, a hypermedia-driven agent cannot perform it, even though it might be possible. Since machine clients lack the flexible coping strategies of humans, they cannot complete the interaction through alternative means. For that reason, agents are currently preprogrammed to perform tasks spanning different applications, leading to tight conversational coupling [4].
Affordance coupling is an excellent example of the often overlooked trade-off. REST’s architectural benefits indeed come at a cost.
This brings us to the inconvenient conclusion that the application of the hypermedia constraint on the Web’s publisher-driven linking model is problematic: the sole party responsible for generating the affordance toward next steps is unable to do this optimally for any specific client. We have called this the Web’s affordance paradox [5]. Similarly, while the REST architectural style decreases conversational coupling when compared to RPC-style interactions [4], it introduces affordance coupling [6]. The fact that a client should be able to complete any interaction through hypermedia puts a heavy constraint on the server, which cannot be fulfilled on the open Web. Clearly, we must either abandon the hypermedia constraint and the desirable architectural properties it induces, or find a way around its apparent contradiction with the Web’s implementation of hypermedia controls.
As a matter of fact, the Web is the application.
The problem arises partly because hypermedia as the engine of application state
implicitly assumes that this application state belongs to a single server. Given the relevant controls and semantic descriptions, autonomous machine clients can indeed use a single application in a hypermedia-driven way, as demonstrated before. Yet on the current Web, it has become impossible to confine application state to the boundaries of a single application. Instead, we should envision application state on a Web scale, where the affordance provided by a piece of information is distributed across different Web applications. This then transforms hypermedia affordance into a subjective experience, not imposed by the publisher, but created around the client.
In this chapter, we introduce our solution to the affordance paradox. First, we provide an overview of related approaches and their shortcomings. Next, the concept of our approach is detailed, followed by its architecture and two implementations. The proposed framework is then evaluated through a user study. We conclude with a discussion of its advantages and drawbacks and explain how semantic technologies and hypermedia work together.
Toward more flexible links
Affordance mismatches and the involved actors
In contrast to Gibson [2], who considers all action possibilities, even those (seemingly) inaccessible for a subject, Norman is focusing on the perceived affordance [1].
Before inspecting methods to augment the affordance of hypermedia representations, we should understand why clients sometimes cannot complete actions. We identify three distinct possible causes [6]:
-
The affordance is present but unused.
Such a mismatch occurs when a person cannot find a link or when a machine doesn’t understand its semantics. -
The affordance realizes the action with a different provider.
A client might have a certain action in mind that is afforded by the representation, yet not in the preferred way. -
The affordance is not present.
In this case, the action cannot be completed through hypermedia at all, so the user must fall back to other mechanisms.
For example, a publisher offers a photograph that the client wants to crop with the online image application ImageApp, one of the many providers.
All of the above three causes involve the following actor groups:
- The publisher offers a representation of a resource and, in the Web’s linking model, its associated affordance.
- The client consumes this representation and depends on the affordance therein to perform subsequent actions.
- The provider is one of possibly many that offer an action desired by the user; this actor can be the publisher itself or a third party.
The first of the three causes is the result of the client’s capabilities, which the publisher can accommodate for with various strategies, such as usability improvements for humans or semantic descriptions for machines. The second and third causes concern objectively missing affordances and therefore highlight those cases that require dedicated solutions.
The current Web closely couples the three actors because of its unidirectional linking model.
For the second cause, one option is to allow an interactive choice of the action provider. However, such solutions fall short for the third cause, as their implicit assumption is that, regardless of the provider, a publisher can foresee all possible actions a user might want to perform. Therefore, the second cause is actually a corner case of the third, especially if we consider the client’s desired action the combination of an intention and a specific provider.
Compromises and trade-offs might of course prove necessary. Our goal is to maximize the affordance with minimal coupling.
Consequently, we should especially keep the third cause in mind when looking at possible solutions. For complete flexibility, resources should be able to afford any action with any provider, regardless of the specific application scenario the publisher had in mind when designing the interaction.
Adaptive hypermedia
The invention of the Web heralded the end of core hypermedia research, to the extent that the Web is considered the hypertext system.
Before the Web was invented, fundamental hypertext research was flourishing [7], yet the rise of a global hypertext system made much of it obsolete. At least one discipline survived the Web’s revolution: adaptive hypermedia, the research field of methods and techniques for adapting hypertext and hypermedia documents to users and their context [8, 9]. Adaptive hypermedia originated in the context of closed hypermedia systems, in which the document set is under central control and hence modifiable according to an individual’s properties. This is referred to as closed-corpus adaptation, in contrast to adaptation on open corpora such as the Web. Broadly speaking, we differentiate between adaptive presentation, modifying the content to the user’s characteristics, and adaptive navigation support, changing the hypermedia controls inside documents. Solutions to the affordance paradox clearly belong to the latter group of techniques.
A simple link annotation method commonly seen on the Web is coloring already visited hyperlinks to visually signal where a user has been before [10].
Adaptive navigation support systems can be subdivided into five categories [10]: direct guidance, link ordering, link hiding, link annotation, and link generation. The last category consists of three kinds of approaches: discovery of new links, similarity-based links, and dynamic recommendations. Our envisioned solution falls into the third group, but differs from existing solutions in the following aspects. Whereas adaptation techniques focus on linking related static documents together, we want to provide controls that afford actions on the current resource. Furthermore, adaptation methods are normally characterized by a specific kind of knowledge representation [8]. Instead, we strive to decouple the information needed for adaptation from specific representation formats in order to enable flexible reuse. But most importantly, a generation strategy that aims to solve the affordance paradox needs to be open-ended on both sides of the generated controls. This means that any resource should be able to afford any possible action, thereby allowing adaptive link generation on open corpora such as the Web.
Leading adaptive hypermedia researchers identified adaptive Web-based systems as an important future direction [11].
Open-corpus adaptive hypermedia has been identified as an important challenge [9], and Semantic Web technologies are considered a possible solution to help overcome the problem of adaptation on an open corpus [12]. In particular, ontologies and reasoning were deemed important [13], because of the initial interest in connecting static documents. Examples of ontology-based systems are COHSE [14], which has a static database for linking, and SemWeB [15]. Both of them can only generate links to related documents.
Structure-based linking
OpenURL was created at Ghent University in the late 1990s and has now been adopted globally.
Identification and retrieval used to be a hard problem before the invention of the Web. URLs have solved this by coupling identification and location, which enables the Web’s straightforward mechanism of hyperlinking. However, there are cases when we deliberately want to separate the two aspects. Bibliographical information is a prominent example, as many institutions have their own article library. When you click a link inside an information source towards an article, you want to consult the copy bought by your institution, not an external version that might require payment. The OpenURL standard [16] started as an initiative to provide dynamic and open links to bibliographical items [17]. Even though its broadest implementation pertains to bibliographical items, it evolved into a generic solution to provide various services on a specific piece of content [18]. OpenURL bears a strong resemblance to the concepts introduced in this chapter, the main difference being the technology stack and hence the possibilities for extension. Using semantic technologies, functionality-based matching and composition of services becomes possible.
Documents containing collections of inbound and third-party links are called link databases, or linkbases.
[19]
The drawbacks of the Web’s choice for a simple linking model have been studied before: links are static, directional, single-source, and single-destination [20]. As these shortcomings could not be solved by modifying the original documents, the idea came to describe the relations between resources in separate documents called linkbases. The XLink was created for this purpose [19]. It separates the concept of association from traversal by providing a structure to indicate the relatedness of several resources, and another to detail arcs from resources to others. A client can then augment a representation with additional links by consulting such a linkbase. To identify what exactly should be linked, the XPointer allows to indicate specific fragments in XML-based documents [21] such as certain elements or words. However, the concept has two inherent issues. First, the use of XPointer restricts the representations to XML documents, and in general, XPointer is highly dependent on a specific representation. As such, if the structure of a representation changes, the method breaks. Second, the linkbase concept implies that there is a party who is knowledgeable of the resources involved in the relation (and also of their representations). Hence, if it wants to connect resources from two applications, it needs to know both of them, so dynamic action generation on the open Web remains impossible.
External interactions through widgets
An abundance of Like and Tweet buttons follows us around the Web. They are in fact affordances created by third parties, yet the publisher of information still has to decide on their inclusion on a page.
© Facebook / Twitter
Since around 2000, the Web started evolving toward an interactive medium in which visitors contribute to the content of websites. Particularly the advent of social networks, which encourage users to exchange various snippets of content with friends and acquaintances, have turned regular users into independent content creators. Part of the experience is to share and comment on content from elsewhere on the Web. To facilitate these activities, social networks offer widgets, such as Facebook’s Like button [22] or Twitter’s Tweet button [23], which form a very prominent form of external affordances on today’s Web. We consider them external because they are commonly included in HTML representations as script or iframe tags with a source URL that leads to an external domain, classifying them as embedded link hypermedia factors [24]. Some of those widgets demonstrate personalized affordance; for instance, Facebook can personalize its button with pictures of the user’s friends with links to their profiles. However, the decision as to what widgets should be included must still be taken by the information publisher, so the affordance remains publisher-driven. An additional issue is that different applications demand different metadata for optimal widget integration, which can make adding widgets costly [25].
In order to avoid the choice between different widgets and to vastly simplify their integration, services such as AddThis [26] offer personalized widgets to different social networking sites. Publishers only have to include one external script to provide access to many different interaction providers. Visitors who have an AddThis account may indicate their preferred sharing applications, which are then shown on visited pages that include the AddThis code. While solving the issue of interfacing to several providers, the offered actions still remain limited to what AddThis supports. Furthermore, the service doesn’t exploit specific content characteristics, as all offered actions are very generic and mostly restricted to social network activities.
The discussion surrounding social networks and privacy is frequently featured in the media. An all too obtrusive integration of many social widgets in websites raises questions on their desirability.
An undesired side-effect in the case of social network widgets is that users’ privacy can be compromised. When share buttons are clicked, the social networking site of course has evidence of what content a user interacts with, which can be used for targeted advertising. Even more concerning is that users are already tracked by merely visiting a website with a social widget if they are logged in to their account [27], precisely because the widget script comes from an external source. Personalized affordance should not imply the exposure of one’s personal preferences to third parties.
Web Intents
The Web Intents proposal originated from Google. In response, Mozilla has coined Web Activities [28], specifying the delegation of actions, regardless of discovery or protocol.
A technology that allows specific actions to be embedded in websites is Web Intents [29, 30], which aim to offer a Web version of the Intents system found on Android mobile devices. There, Intents are defined as messages that allow Android components to request functionality from other components
[31]. With Web Intents, Web applications can declaratively specify their intention to offer a certain action, and websites can indicate they afford this action. For example, social media sites can state they enable the action share
, and a photo website can offer their users to share pictures. When users initiate the share
action on the website, the Web Intents protocol then allows them to share the photo through their preferred supporting application. In contrast to AddThis, more content-specific actions become possible, such as editing, viewing, subscribing, and saving.
Web Intents address the choice of a provider, but not users’ preference for a certain action.
Although Web Intents’ goals are similar to ours, there’s a crucial difference in their architecture that severely limits their applicability. The benefit of Web Intents is that they are scalable in the number of action providers—without Web Intents, publishers have to decide which action providers they support. For instance, the publisher of the photo website would have to decide which specific sharing applications it would offer its users. With Web Intents, users can share photos through their preferred application, without the publisher having to offer a link to it. A major drawback of Web Intents is that they do not scale in the number of actions. Although the OpenIntents initiative allows to define custom actions [32], a publisher still has to decide which actions to include. In the photo website example, the publisher might opt to include a share
action, but that is not useful if users want to order a poster print of a picture, download it to their tablet, or edit it in their favorite image application. Due to the design of Web Intents, there is no way to infer other possible actions on the current resource based on the publisher’s selection.
Despite enthusiasm from its users and developers, Web Intents support has been removed from the Chrome browser.
While this strategy works on a platform such as Android, where the set of possible actions is limited to those offered by the device, such a closed-world assumption cannot hold on a Web scale. Summarizing, we can say that Web Intents do not solve the core issue: a publisher still has to determine what affordances a user might need. The problem thus shifts from deciding which action providers to support to deciding which actions to support. Therefore, Web Intents only offer personalized affordance to a limited extent—
Distributed affordance
Concept
While users can construct actions manually, simply clicking through takes far less effort and is how the Web is supposed to work.
Our solution to the affordance paradox is inspired by the typical user behavior when desired affordance is missing in the hypermedia representation. For example, suppose a user wants to edit a photo on a website through a specific online application. Unaware of the user’s intentions, the publisher didn’t supply a hypermedia control for this. Lacking an actual control, the user completes the interaction in an alternative way. One coping strategy would be to copy the image’s URL, using the browser’s address bar to navigate to the application, and paste the URL into a designated control there. This common scenario is possible because the user on the one hand knows the application supports photo editing, and on the other hand recognizes the current object as a photograph.
The above example illustrates that a lack of affordance to execute the action does not imply a lack of information. It does mean that the affordance for this action does not reside in the representation itself, but must rather be crafted manually by combining non-actionable information in that representation and out-of-band knowledge about the action provider. To automate this process, the representation should be machine-interpretable, and the provider’s action should be described in a machine-interpretable way. Based on a match between a resource’s content and the descriptions of actions, affordances to those actions can be generated.
Analogous to how human understanding of a representation allows to find actions, semantic annotations guide machines to make content actionable in a personalized way.
Distributed affordance [5] is the concept of automatically generating hypermedia controls to realize actions of the client’s interest, based on semantic information about resources inside hypermedia representations. Publishers should provide semantic annotations in representations, and action providers’ services should be described semantically, so an automated client is able to infer which actions are applicable on the current resource. This allows the generation of affordances toward these actions, which are then intertwined with the representation. To account for the preferences of individual clients, the matching should happen in a personalized way.
This method is distributed because the affordance originates from distributed sources, without requiring a central linkbase to connect documents and actions. Support for new actions and providers can be added without changing any components, as the decision whether an action matches a resource happens locally. Some form of understanding of the representation is required, but the annotations are not specific to distributed affordance.
Process
The task of a distributed affordance platform is to generate personalized hypermedia controls for the client. To this end, it needs to address the following subproblems:
- extracting non-actionable information from the representation;
- organizing knowledge about actions offered by providers;
- capturing a client’s action preferences;
- combining non-actionable information and provider-specific action knowledge into possible actions;
- integrating affordance into the original representation.
In case annotations are missing, they could be extracted using named-entity recognition [33].
All of the above should happen in a scalable way. Before the process can start, the preconditions below must be satisfied:
- The representation contains some form of semantic annotations. Either the representation is structured in a machine-interpretable format such as RDF (if the client is a machine), or either it contains semantic markup (such as HTML with RDFa).
- Provider actions are described semantically in a functional Web API description format (such as RESTdesc). These descriptions can be created by the provider or by third parties.
- The client has a collection of such descriptions that correspond to preferred action providers. For instance, they could be obtained by a process similar to bookmarking; instead of a hyperlink to a provider’s page, the action description is stored.
In all steps, the platform only needs access to local knowledge. This means that the affordance generation happens in a fully distributed way.
Automated affordance creation happens through the steps below:
- After the client has received the representation from the publisher, it is inspected by the distributed affordance platform.
- The platform extracts semantic entities from the representation, using format-specific parsers (RDF, RDFa, Microdata, …) and converts them to triples. This allows to maintain the semantic information during the entire process.
- Using Web API matching, descriptions that can act upon the extracted entities are selected.
- Matching descriptions are instantiated with the specific entities found in the representation, thereby becoming a concrete action instead of an abstract description.
- Controls toward the instantiated actions are created and interleaved with the representation.
After this process, the client has access to the augmented representation and can directly perform its preferred actions.
Architecture
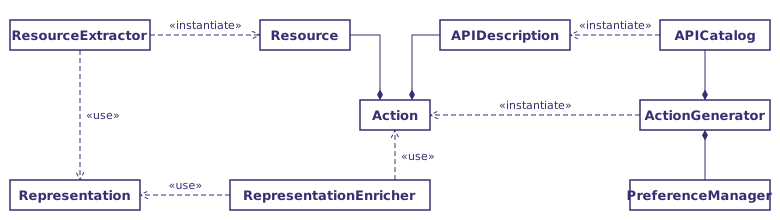
The components of the platform’s architecture can be grouped in five functional units, which are discussed below.
Information extraction
Representations can contain resource descriptions of people, movies, books, images, addresses, …
A ResourceExtractor extracts RDF triples from a representation. ResourceExtractor itself is only an interface, as several annotations are possible. For textual representations, extractors could for instance use named-entity recognition techniques.
Action provider knowledge
Functional Web API descriptions are maintained by one or multiple APICatalog implementations, each of which supports a specific method. The information in these descriptions should be structured in such a way that, given certain resource properties, it is simple to decide which APIs support actions on that resource.
User preferences
A basic preference option is bookmarking; other implementations could use social recommendation.
A PreferenceManager keeps track of a user’s preferences and thereby acts as a kind of filter on the APICatalog, typically selecting only certain APIs and sorting them according to appropriateness for the user. The role of the PreferenceManager can be taken care of by the APICatalog, which then only includes API descriptions that match the user’s preferences.
Action generation
Each of the action generator implementations is tied to a specific Web API description method.
Based on a user’s preferences, ActionGenerator components instantiate possible actions, which are the application of a certain API on a specific set of resources. Thereby, every action is associated with one or more resources inside the representation.
Affordance integration
Finally, RepresentationEnricher implementations add affordances for the generated possible actions to a hypermedia representation that is sent to the user. Through these affordances, clients can choose and execute desired actions directly. Implementations depend on the media type of the desired representation, as they need to augment its affordance in a specific way.
Action generation
In order to generate actions, we must match and instantiate an API description with extracted resources. Different implementations are possible; we will demonstrate the mechanism with RESTdesc descriptions. Recall from Chapter 4 that RESTdesc also offers a non-hypermedia-oriented way to describe Web APIs:
The antecedent does not contain a link (because there is none), but rather captures a resource, for which a possible action is described.
{ ?book dbpedia-owl:isbn ?isbn. }
=>
{
  _:request http:methodName "GET";
            http:requestURI
              ("http://books.org/" ?isbn "/cover");
            http:resp [ http:body _:cover ].
  ?book dbpedia-owl:thumbnail _:cover.
}.
The ISBN number could be expressed in different vocabularies; ontologies can provide the mapping.
In this case, starting from a book’s ISBN number, the description explains how to obtain its thumbnail image. Note how this can be any book resource from any application anywhere on the Web, as long as we know its ISBN number. For instance, suppose we extract the following triple from a representation:
The extraction result is independent of the original representation format.
<#catcher> a dbpedia:Book;
           foaf:name "The Catcher in the Rye"@en;
           dbpedia-owl:isbn "978-0316769488".
Then any N3 reasoner can automatically match and instantiate the Web API description above as:
_:request1 http:methodName "GET";
           http:requestURI
     ("http://books.org/" "978-0316769488" "/cover");
           http:resp [ http:body _:cover1 ].
<#catcher> dbpedia-owl:thumbnail _:cover1.
To generate user-friendly links, we could add metadata to the API description, such as an action title like Buy this book
.
Thus the book description affords a GET request to http://books.org/
Implementations
Because the method only needs local knowledge to generate affordance, we can choose between two implementation strategies [34]. On the one hand, we have the server-based approach, as necessarily followed by most adaptive hypermedia solutions and widgets such as AddThis. On the other hand, we can take a client-based approach like Web Intents, while maintaining full adaptation flexibility.
Implementations of the server-based approach can be considered affordance as a service. In this case, the publisher explicitly indicates that it wants to provide distributed affordance for a client. For instance, an HTML document could contain the following:
<div id="book" itemscope itemtype="http://schema.org/Book">
  <span itemprop="name">The Catcher in the Rye</span>
  written by <a href="/authors/salinger/" itemprop="author">J.D. Salinger</a>
</div>
<div class="affordances" data-for="book"></div>
<script src="http://shim.distributedaffordance.org/"></script>
The central application distributedaffordance.org acts as a broker between different platform implementations from which the user can then choose. In the example scenario, only vyperlinks.org needs to know about the user’s preferences.
Note the semantic markup with Microdata, which can serve other purposes besides generating affordance. In addition, the publisher has placed a div container with the marker class
, and the affordances
identifier that points to the information source. This container is a placeholder for generated affordance. Using a so-called shim script, the user’s personalized affordances are generated. We have chosen for http://distributedaffordance.org/ as a coordinating hub that can delegate to different platforms. As an example platform, we created http://vyperlinks.org/. The idea is that the user registers for an account with a platform of choice, which then inserts affordance to preferred actions inside the bookaffordances container.
The screenshot below shows an example of affordances generated by vyperlinks.org on a page that contains information about a book.
The shim script verifies whether the client offers affordance generation before deciding to activate the server-side version.
The problem of affordance as a service is that the information publisher must explicitly ask for its support. The other option is to add client-based distributed affordance by extending the client software, for instance through a browser plugin. The benefit is that any page on the Web can be adapted, regardless of whether the publisher has foreseen an affordance placeholder. The drawback is that users need to install the extension to experience the generated affordances.
As it might be difficult to determine where the affordances should be placed on any given webpage, generated links can be offered in a context-sensitive way, for instance, in a popup menu or sidebar. The screenshot below shows a version of an extension for the Chrome browser. Every page that contains RDFa or Microdata markup is equipped with matching actions that can be triggered on demand.
A website can advertise it affords certain actions, which a distributed affordance platform can apply to any resource; similar to Web Intents, but without central coordination.
A potential issue with this implementation is that the links are not intertwined with the content (as would be the case on webpages). When the user hovers over an item, the extension highlights the related links. Further usability testing should reveal whether sidebar-based hyperlinks are sufficient for day-to-day use.
New actions can be added to the extension through the same affordance mechanism: a webpage or document describes a Web API, which is picked up by the extension. The last is then able to discover this API description, and can suggest to remember it for the user. For example, this could enable an online book store to offer the buy this book
action. If users like purchasing through this store, they can add that action to their preferences for direct future use.
User study
This study was conducted together with the team of Peter Mechant at MICT.
While the properties of the platform have been analyzed during the architectural discussion, and the feasibility is demonstrated by the implementations, we still need to validate whether the generated links positively influence people’s browsing behavior. We have conducted a user study to investigate the usage of links, assuming situations wherein people have a certain need that matches a previously created user profile. When designing the study, we needed to choose between a quantitative or a qualitative approach. At first, we were inclined to set up a quantitative experiment to obtain statistical data on users’ efficiency increase.
Participants would spend remarkably more time on tasks they seemed to like, regardless of whether the platform was activated.
However, attempts to measure the time spent performing a task in early experiment trials revealed the timing variance for individuals on different tasks was far too high for generalizable conclusions. Instead, we focused on qualitative parameters in order to learn from people’s experiences by performing an in-depth experiment with a smaller group.
Setup
Following Degler [35], who evaluated methods for improving Semantic Web interaction design, we performed usability tests and interviews with sixteen users in their home or professional setting. The aim of the study was to evaluate the suitability of the distributed affordance platform for ordinary
Internet users, and to explore how users experience and apply the affordances of the platform.
The exploratory study was designed as a repeated-measures two-factorial quasi-experiment with two levels for each factor, meaning participants were involved in every condition or factor of the research [36]. The first factor was the platform itself, where participants completed simple tasks with or without the platform enabled. The second factor was briefed or non-briefed, where the tasks were presented to Internet users who were briefed on distributed affordance and to Internet users who were not. In order to collect consistent data from each participant, we programmed a proxy server in such a way that for each scenario, the platform was activated in 2 out of 4 tasks the participants had to complete.
The complete interview setup and questions are detailed in a complementary appendix [37].
The study employed a multimethod approach [38] combining three research and analysis methodologies: observation, survey, and interview. These methods are complementary, yet offer different forms of data. We were particularly interested in the use and usability of distributed affordance, in observing which of the navigation options subjects used, and in gathering information about overall perceived usefulness and enjoyment of the platform.
Participants
We were curious for the difference between low- and high-skilled users, as we assumed that the latter group would have better coping strategies when the affordance is missing.
Sixteen Web users participated and were subjected to the quasi-experiment in their home or professional setting. All participants were volunteers and received a gift voucher for taking part in the research. We briefly screened the participants beforehand to ensure that users with Web skills varying from low to high were included. All participants were observed while completing four simple tasks online. Afterwards, they were interviewed and asked to complete an online survey.
The participants’ mean age was 35.8 years (), and 56% was female. On average, the participants have been using the Internet for more than 10 years. Among them, 13 owned a desktop computer and 14 a laptop, while 12 owned a smartphone and 7 a tablet. Chrome was the preferred browser of 9 people, followed by Internet Explorer (4 people) and Firefox (3 people).
Material
We would actively listen whether the participants noted the presence of the generated links (although they could not recognize them as such).
For each participant, we randomly selected two out of four tasks for which the platform would provide enrichment; for the remaining two tasks, we deactivated the platform. We used a proxy server to implement distributed affordance hyperlinks into the chosen websites, as not all of the websites provided the semantic annotations necessary for the regular platform. As these hyperlinks were embedded unobtrusively in the layout of the website, clicking the suggested links was intuitive, but not enforced. Furthermore, the participants had no explicit means of noticing whether the platform was active or not. They were allowed to use their browser of choice in order to replicate their usual browsing habits [39].
We asked participants to complete the following tasks in a varying order on a portable computer:
- book task – starting from a book review site, buy a book of choice;
- restaurant task – starting from a restaurant review site, find directions to a restaurant of choice;
- cinema task – starting from a cinema website, find the age of an actress in a specific movie;
- sharing task – starting from a cartoonist website, share a cartoon of choice on Facebook or Twitter.
These tasks were chosen to reflect common activities on the Web that many of the participants could relate to. For the sharing tasks, social media profiles were created as to not oblige participants to have and use a personal account.
Methodology
In the first phase of the study, we conducted semi-structured, in-depth interviews to gain insights in the browsing behavior of the participants. In addition to questions on media ownership, knowledge of Internet browsers, and Internet use, we implemented questions derived from media literacy research in order to assess the participants’ Web skills in detail [35, 40].
The Think Aloud Protocol was particularly helpful to understand participants’ reasoning regarding why certain links were clicked.
The second phase of the study consisted of the participants—
In a third and final phase, a short debriefing interview was held to gauge the participants’ requirements, expectations, experiences, perceived advantages and disadvantages of the platform. Non-briefed participants were informed first on the distributed affordance concept. All participants were asked if they could distinguish the specific tasks for which the platform was activated. Next, we confronted them with the presence of the platform in each task, asking them what they would have done if the link was not suggested. To conclude the interview, the platform was evaluated using a short survey that implements the System Usability Scale [42, 43] as well as the Mean Opinion Score approach [44].
Results and discussion
Almost all participants, briefed or not, followed the links suggested by the platform as those enabled them to achieve and complete the tasks faster and more efficiently. Most participants expressed the feeling that Web links should be adjusted to their individual needs and were satisfied to find these direct links present on the websites in the distributed affordance-enabled tasks. When the platform was not activated for a given task, various participants spontaneously indicated or complained about the lack of direct hyperlinks.
While observing the participants executing the tasks, we noticed differences in self-efficacy and self-confidence between participants with high and low Web skills. However, these differences were not reflected in the interviews or answers to the survey and neither in participants’ appreciation of the platform.
A participant exclaimed she couldn’t complete the sharing task because she never used Twitter, only to then find the direct link and still succeed.
If the platform was not activated, almost all participants used Google when performing the restaurant, cinema, and book task. When performing the sharing task, some participants copied and pasted the image URL; others downloaded the image to the computer and subsequently uploaded it to the Facebook/
Of course, I clearly prefer distributed affordance, because it eliminates a number of extra steps […]. I always want to find things fast and it becomes very annoying if you need to take a lot of steps to reach your goal. On a fixed device, you have lots of screen space and input options, but on a smartphone, your screen is a lot smaller and the keyboard is a lot clumsier.
It sometimes happened that distributed affordance links were present for the completion of the task, but they were not followed—
The demand for privacy can be met by the client-side implementation, as all preferences would be stored locally.
Participants indicated that they did not perceive or experience the suggested links as annoying or cumbersome (in contrast to Web advertising links). However, some other concerns were voiced. One concern raised by almost half of the participants was privacy, and this was related to the private or personal information users need to disclose in order to experience the personalized character of the platform. Another concern raised during the interviews was on potential constraints the platform can impose. Concretely, because the platform eliminates the different steps that need to be executed toward the completion of the tasks in a regular browsing context, the potential of accidentally finding new or unrelated information during this searching process is lost when using distributed affordance.
If a user’s profile contains several providers, direct links to different shopping sites can actually appear; a lowest price
service can even be one of them. Therefore, buying items at the best price would be a possible feature.
Also, four respondents expressed concerns that, for the purchase of consumer products, the platform could be exploited by commercial organizations. In the words of Jenna, a 25 year old city official:
No, I don’t think I would use this system to shop or buy products, shoes, or books for example… I would rather prefer to first have a look at various shopping sites, to compare prices and user comments. […] With this system, I would feel limited and I might pay too much for my books.
A minority of three participants stated that the platform might prove to be too much
and might give rise to an information overload for the Internet user. In this context, Piet, a 59 year old civil servant, told us the following:
Sometimes I do not need or want additional hyperlinks on the webpage because I know the solution or the appropriate link myself. In those cases, the hyperlinks provided by the platform become ballast.
Although executing the task through the generated links might still be faster, finding the right link among many others might become difficult. Therefore, it is crucial the links are highly personalized and specific. An important future research task should thus be to investigate how preferences can be determined and applied to concrete situations.
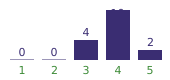
The Mean Opinion Score’s distribution reveals that participants appreciate the platform’s functions.
Despite these concerns, the overall evaluation and the experiences and perceived advantages of the sixteen participants were quite positive and pointed to the platform as a functional system that is perceived as an enrichment for the Internet user (especially for those who want to browse faster or more efficiently). This is also reflected in the survey results: almost all of the participants rated their experience with the platform as good, as evidenced by a Mean Opinion Score of 3.875 () on a scale of 1 (poor) to 5 (excellent). The platform’s score on the System Usability Scale, a scale for assessing system usability ranging from 0 to 100, was very high to excellent with an average of 84. This allows us to conclude that distributed affordance has the intended effect on users of the platform. Furthermore, the gained feedback will guide future developments.
Advantages and drawbacks
The strongest feature of distributed affordance is its focus on open corpus adaptive navigation generation, which is realized through semantics.
As a final step, we will provide an overview of the advantages and drawbacks of the proposed distributed affordance platform. Regarding the functional aspect, the platform offers the benefit of being able to combine any resource with any possible action. This contrasts with traditional adaptive hypermedia methods, which usually consider consulting a related document
as the only action. Similarly, social widgets and related interfaces focus on variants of the share
action, which applies to any resource type. Web Intents goes further by supporting an action set that allows extension; however, only actions explicitly indicated by the information publisher can be activated on any given resource. Because the matching for distributed affordance is based on the semantic interpretation of resources and actions, new action types can be supported directly.
On the architectural level, distributed affordance has the advantage that it does not require an omniscient server, as is the case with most open-corpus adaptive hypermedia methods, which generally use proxy servers. Since distributed affordance can run locally, it scales with the number of clients, without putting extra strain on any server. It shares this benefit with widgets and Web Intents.
Before entity extraction methods can replace semantic annotations, their accuracy must improve.
The major drawback of the platform is its dependency on the same feature that gives it its power: semantic technologies. In all fairness, the potential benefits of semantic annotations have not sufficiently convinced Web publishers yet. Therefore, relying on the presence of these annotations can be troublesome. In that regard, a crucial decision for distributed affordance has been to rely on existing markup techniques instead of inventing a proprietary mechanism. We trust that the other features brought by annotations, such as better searchability and interaction, will provide the necessary incentives to provide some form of markup in the future [25].
An equivalent of named-entity extraction, targeting actions instead, could prove a viable direction.
The need for semantic Web API descriptions is probably the most pressing: as discussed in Chapter 4, many approaches exist—
The Web provides affordance on an unforeseen scale: any document can link to any other, regardless of where in the world the latter is located. Yet, the Web’s publisher-driven linking model increasingly falls short as the need grows to act on resources through different Web applications in ways that the information publisher could not foresee. The proposed distributed affordance platform offers a linking strategy based on machine interpretation of a resource and its match to possible actions. The automatic generation of personalized, relevant affordances on the open corpus of the Web thereby becomes possible, but it depends on the availability—
References
- [1]
- Norman, D.A. (1988), The Design of Everyday Things, Doubleday, New York.
- [2]
- Gibson, J.J. (1979), The Ecological Approach to Visual Perception, Houghton Mifflin.
- [3]
- Fielding, R.T. (2000), Architectural Styles and the Design of Network-Based Software Architectures, PhD thesis, University of California, available at: http://www.ics.uci.edu/~fielding/
pubs/ .dissertation/ top.htm - [4]
- Pautasso, C. and Wilde, E. (2009), “Why is the Web loosely coupled? – A multi-faceted metric for service design”, in Proceedings of the 18th International Conference on World Wide Web, ACM, New York, pp. 911–920, available at: http://www2009.eprints.org/
92/ .1/p911.pdf - [5]
- Verborgh, R., Vandenbroucke, K., Mechant, P., Mannens, E. and Van de Walle, R. (2014), “Addressing the Web’s Affordance Paradox with Linked Data and Reasoning”, Springer.
- [6]
- Verborgh, R., Hausenblas, M., Steiner, T., Mannens, E. and Van de Walle, R. (2013), “Distributed Affordance: An Open-World Assumption for Hypermedia”, in Proceedings of the 4th International Workshop on RESTful Design, pp. 1399–1406, available at: http://www2013.org/
companion/ .p1399.pdf - [7]
- Conklin, J. (1987), “Hypertext: An Introduction and Survey”, Computer, Vol. 20 No. 9, pp. 17–41, available at: https://doi.org/
10.1109/ .MC.1987.1663693 - [8]
- Brusilovsky, P. (1996), “Methods and techniques of adaptive hypermedia”, User Modeling and User-Adapted Interaction, Kluwer Academic Publishers, Vol. 6 No. 2–3, pp. 87–129, available at: http://dx.doi.org/
10.1007/ .BF00143964 - [9]
- Brusilovsky, P. (2001), “Adaptive Hypermedia”, User Modeling and User-Adapted Interaction, Kluwer Academic Publishers, Vol. 11 No. 1–2, pp. 87–110, available at: https://doi.org/
10.1023/ .A:1011143116306 - [10]
- Brusilovsky, P. (2007), “Adaptive navigation support”, in Brusilovsky, P., Kobsa, A. and Nejdl, W. (Eds.), The Adaptive Web, Springer-Verlag, pp. 263–290, available at: http://dl.acm.org/
citation.cfm?id=1768197.1768207 . - [11]
- De Bra, P., Aroyo, L. and Chepegin, V. (2004), “The Next Big Thing: Adaptive Web-Based Systems”, Journal of Digital Information, Vol. 5 No. 1, available at: http://wwwis.win.tue.nl/~debra/
jodi2004/ . - [12]
- Brusilovsky, P. and Henze, N. (2007), “Open corpus adaptive educational hypermedia”, in Brusilovsky, P., Kobsa, A. and Nejdl, W. (Eds.), The Adaptive Web, Springer, pp. 671–696, available at: http://dl.acm.org/
citation.cfm?id=1768197.1768223 . - [13]
- Dolog, P. and Nejdl, W. (2007), “Semantic Web technologies for the adaptive Web”, in Brusilovsky, P., Kobsa, A. and Nejdl, W. (Eds.), The Adaptive Web, Springer, pp. 697–719, available at: http://dl.acm.org/
citation.cfm?id=1768197.1768224 . - [14]
- Yesilada, Y., Bechhofer, S. and Horan, B. (2008), “Dynamic Linking of Web Resources: Customisation and Personalisation”, in Wallace, M., Angelides, M.C. and Mylonas, P. (Eds.), Advances in Semantic Media Adaptation and Personalization, Vol. 93, Studies in Computational Intelligence, Springer, pp. 1–24, available at: https://doi.org/
10.1007/ .978-3-540-76361_1 - [15]
- Şah, M., Hall, W. and De Roure, D.C. (2008), “Designing a Personalized Semantic Web Browser”, in Nejdl, W., Kay, J., Pu, P. and Herder, E. (Eds.), Adaptive Hypermedia and Adaptive Web-Based Systems, Vol. 5149, Lecture Notes in Computer Science, Springer, pp. 333–336, available at: http://dx.doi.org/
10.1007/ .978-3-540-70987-9_47 - [16]
- The OpenURL Framework for Context-Sensitive Services, NISO standard No. ANSI/
NISO Z39.88-2004. (n.d.). , NISO, available at: http://www.niso.org/ standards/ .z39-88-2004 - [17]
- Van de Sompel, H. and Hochstenbach, P. (1999), “Reference Linking in a Hybrid Library Environment – Part 2: SFX, a Generic Linking Solution”, D-Lib Magazine, Vol. 5 No. 4, available at: http://www.dlib.org/
dlib/ .april99/ van_de_sompel/ 04van_de_sompel-pt2.html - [18]
- Van de Sompel, H. and Beit-Arie, O. (2001), “Generalizing the OpenURL Framework beyond References to Scholarly Works”, D-Lib Magazine, Vol. 7 No. 7, available at: http://www.dlib.org/
dlib/ .july01/ vandesompel/ 07vandesompel.html - [19]
- DeRose, S., Maler, E. and Orchard, D. (2001), XML Linking Language (\xlink) Version 1.0, Recommendation, World Wide Web Consortium, available at: http://www.w3.org/
TR/ .xlink/ - [20]
- Lowe, D. and Wilde, E. (2001), “Improving Web Linking Using \xlink”, in Proceedings of the Open Publish Conference, available at: http://dret.net/
netdret/ .docs/ OpenPublish2001.pdf - [21]
- DeRose, S., Maler, E. and Daniel, R., Jr. (2001), XML Pointer Language (XPointer) Version 1.0, Candidate Recommendation, World Wide Web Consortium, available at: http://www.w3.org/
TR/ .2001/ CR-xptr-20010911/ - [22]
- Facebook. (n.d.). “Like Button”, available at: https://developers.facebook.com/
docs/ .reference/ plugins/ like/ - [23]
- Twitter. (n.d.). “Tweet Button”, available at: https://dev.twitter.com/
docs/ .tweet-button - [24]
- Amundsen, M. (2011), “Hypermedia Types”, in Wilde, E. and Pautasso, C. (Eds.), REST: From Research to Practice, Springer, pp. 93–116, available at: https://doi.org/
10.1007/ .978-1-4419-8303-9_4 - [25]
- Verborgh, R., Mannens, E. and Van de Walle, R. (2013), “The Rise of the Web for Agents”, in Proceedings of the First International Conference on Building and Exploring Web Based Environments, pp. 69–74, available at: http://thinkmind.org/
download.php?articleid=web_2013_3_30_40070 . - [26]
- AddThis. (n.d.). “Share Buttons”, available at: https://www.addthis.com/
get/ .sharing - [27]
- Richmond, R. (2011), “As ‘Like’ Buttons Spread, So Do Facebook’s Tentacles”, New York Times Bits blog, 27 September, available at: http://bits.blogs.nytimes.com/
2011/ .09/ 27/ as-like-buttons-spread-so-do-facebooks-tentacles/ - [28]
- Mozilla. (n.d.). “Web Activities”, available at: https://wiki.mozilla.org/
WebAPI/ .WebActivities - [29]
- Billock, G., Hawkins, J. and Kinlan, P. (2013), Web Intents, Working Group Note, World Wide Web Consortium, available at: http://www.w3.org/
TR/ .web-intents/ - [30]
- Kinlan, P. (2010–2013), “Web Intents”, available at: http://webintents.org/.
- [31]
- Android. (n.d.). “Intents and Intent Filters”, available at: http://developer.android.com/
guide/ .components/ intents-filters.html - [32]
- “OpenIntents”. (n.d.). , available at: http://www.openintents.org/.
- [33]
- Nadeau, D. and Sekine, S. (2007), “A survey of named entity recognition and classification”, Lingvisticæ Investigationes, Vol. 30 No. 1, pp. 3–26, available at: https://doi.org/
10.1075/ .li.30.1.03nad - [34]
- Verborgh, R., Verhoeven, M., Mannens, E. and Van de Walle, R. (2013), “Semantic Technologies as Enabler for Distributed Adaptive Hyperlink Generation”, in Late-Breaking Results, Project Papers and Workshop Proceedings of the 21st Conference on User Modeling, Adaptation and Personalization, available at: http://ceur-ws.org/
Vol-997/ .umap2013_lbr_9.pdf - [35]
- Degler, D. (2011), “Design 10:5:2 for semantic applications”, Semantic Technology Conference, available at: http://www.designforsemanticweb.com/.
- [36]
- Gravetter, F.J. and Wallnau, L.B. (2009), Statistics for the Behavioral Sciences, Cengage Learning.
- [37]
- Verborgh, R., Vandenbroucke, K., Mechant, P., Mannens, E. and Van de Walle, R. (2014), “Addressing the Web’s Affordance Paradox with Linked Data and Reasoning – User Study”, available at: http://distributedaffordance.org/
publications/ .user-study.pdf - [38]
- Murthy, D. (2008), “Digital Ethnography: an examination of the use of new technologies for social research”, Sociology, Vol. 42 No. 5, pp. 837–855, available at: https://doi.org/
10.1177/ .0038038508094565 - [39]
- van Deursen, A.J.A.M. and van Dijk, J.A.G.M. (2009), “Using the Internet: Skill related problems in users’ online behavior”, Interacting with Computers, Elsevier Science, Vol. 21 No. 5–6, pp. 393–402, available at: https://doi.org/
10.1016/ .j.intcom.2009.06.005 - [40]
- Hargittai, E. (2005), “Survey Measures of Web-Oriented Digital Literacy”, Social Science Computer Review, Sage Publications, Vol. 23 No. 3, pp. 371–379, available at: https://doi.org/
10.1177/ .0894439305275911 - [41]
- Jääskeläinen, R. (2010), “Think-aloud protocol”, in Handbook of Translation Studies, Vol. 1, John Benjamins Publishing, Amsterdam, The Netherlands, pp. 371–373, available at: https://doi.org/
10.1075/ .hts.1.thi1 - [42]
- Bangor, A., Kortum, P.T. and Miller, J.T. (2008), “An Empirical Evaluation of the System Usability Scale”, International Journal of Human-Computer Interaction, Taylor & Francis, Vol. 24 No. 6, pp. 574–594, available at: https://doi.org/
10.1080/ .10447310802205776 - [43]
- Brooke, J. (1996), “SUS: a quick and dirty usability scale”, in Usability Evaluation in Industry, Taylor and Francis, London, UK, available at: http://hell.meiert.org/
core/ .pdf/ sus.pdf - [44]
- ITU-R. (2003), Method for the Subjective Assessment of Intermediate Quality Level of Coding Systems, Recommendation No. BS.1534-1, available at: http://www.itu.int/
rec/ .R-REC-BS.1534-1-200301-I/ e