
Chapter 7 – Serendipity
Tri martolod yaouank i vonet da veajiñ
E vonet da veajiñ, gê!
Gant ’n avel bet kaset beteg an Douar Nevez Alan Stivell, Tri Martolod (1972)
The Web’s linking of information has alluring effects on the curious: starting from a page, we can click through to anywhere in the world. Many people can recall occurrences of online serendipity—
Serendipity: the faculty or phenomenon of finding valuable or agreeable things not sought for.
© Merriam-Webster
Notoriously one of the hardest words to translate, serendipity
stems from the ancient story The Three Princes of Serendip
. The princes get involved in spectacular adventures, go in the direction of one goal only to arrive at another, but ultimately, everything always ends well. Serendipity seems to imply chance and luck—
Calling serendipity an engineerable property implies some systems are inherently more fit for it than others [2]. To a certain extent, the Web itself was engineered for serendipity. The fact that links can point from one resource to any other, regardless of the server the latter is located on, accounts for many fortunate encounters that wouldn’t be possible in systems with centralized linkbases. Yet at the same time, publisher-driven hyperlink creation deprives us from following connections that would have been created by third parties, which could bring new viewpoints to existing content [3].
So far, we only looked at implementations of distributed affordance with one single user’s choices. Preference exchange in social graphs can lead to truly serendipitous links.
In the previous chapter, we used distributed affordance to bring back interactions by providing controls toward preferred actions. Whether we call this serendipity depends on the interpretation of the word: is it coincidentally finding the things you want, or rather discovering those things you didn’t know you wanted? During the user study we performed, one participant was concerned that the platform, through its attempt to add desired links, would actually remove the need to look around and thus reduce the occasions for discovering new things. This indicates that the way toward a goal might be as important as the goal itself. Fortunately, there are various ways to support both interpretations of serendipity. For instance, actions could be suggested using recommender systems, based on other users of the system with a similar profile.
The Hydra console shows a rare example of a fully generic, non-HTML hypermedia client. It is non-autonomous, providing a user interface over any REST API, given certain annotations [4].
In this chapter, we will focus on bringing serendipity to Web applications and machine clients of those applications. As discussed before, many clients today are preprogrammed for a specific task, making it impossible for them to engage in spontaneous interactions. They can only perform the specific task they were designed for, and as a result, we end up with many applications for many tasks, as opposed to the single Web browser that allows us to manually solve any task. The genericness of REST’s uniform interface lets different clients interact with different applications. Still, we almost always encounter single-purpose clients in practice—
Although it might seem paradoxical, planning for serendipity can lead to flexible reuse [2].
Serendipity can be supported in hypermedia-driven cases if the client indeed tries to discover the possibilities of each representation sent by the server. This implies a degree of freedom in the representation’s format, while still allowing to get a structured message across. Hypermedia can be the engine of application state to a certain extent, but could hypermedia also be sufficient as the engine of serendipity? This chapter will outline a strategic mindset we should adopt if we want to design applications that can collaborate in more flexible ways than currently possible. We start by advocating the combination of hypermedia and semantic technologies, followed by a discussion with examples of what serendipitous Web applications might look like.
Semantic hypermedia
Semantic media types
Well-designed contracts allow for an independent evolution of clients and servers.
Contracts are vital in distributed systems, as they determine the structure of interactions between different parties. In REST systems, the contract is partially fixed by the uniform interface, which stipulates resources as the unit of information, together with the rules on how resource manipulation should happen [2]. The other part is defined by the used media types, which detail the formats, processing model, and hypermedia controls [5]. In fact, REST API design should focus on defining media types and/
As outlined in Chapter 3, there is an inherent trade-off between specificity and reusability: more specific media types carry more detailed semantics, at the cost of being less portable across situations. Therefore, the recommended strategy is to choose the media type with the least expressivity that still fulfills the task at hand. In increasing order of expressivity, we have generic hypermedia types, customizable patterns, and domain-specific solutions [7].
In nearly all use cases, application/json would be too vague: many APIs offer resources that need more accurate typing.
Another issue with generic hypermedia types is that API publishers often treat them as domain-specific types, but label them otherwise. For instance, the publisher of a certain API might label all of its responses as application/json, the standard JSON media type, even though they follow a structure with far stronger constraints than JSON. While technically correct—
Suffixes such as +json can indicate the more generic media type to which representations conform [8]. The vnd prefix indicates a vendor-specific type [9].
However, it is a fallacy that media types eliminate out-of-band information. For instance, that same API could choose instead to return responses in an application/vnd.myformat+json media type, which would provide an interpretation specific to the application. While this resolves the situation in which a client receives a resource in a media type it can parse but not interpret, it doesn’t change the fact that the client must be preprogrammed for this interpretation. After all, media types are usually described in human-readable form. We thus arrive at the paradoxical situation that specific media types are created precisely to eliminate out-of-band information during the interaction, yet the interpretation of the media type itself remains out-of-band. This seriously hinders autonomous agents, which can parse those representations, but not grasp their semantics.
Media types and their corresponding identifier can be registered at the Internet Assigned Numbers Authority (www.iana.org).
One of the four constraints of the REST uniform interface is the use of self-descriptive messages [10]. As we explained in Chapter 2, this reflects in HTTP’s limited method set and standardized metadata fields. We could also consider standardized media types as part of this, as their interpretation is widespread. Domain-specific media types can hardly be called self-descriptive because of the required out-of-band information. However, if we embed the interpretation into the representation of a resource, then the self-descriptiveness constraint becomes fulfilled. With human-targeted media types such as HTML, our understanding of natural language makes representations self-descriptive. For machine clients, we can rely on semantic media types such as RDF variants, which allow for automated interpretation.
We define semantic hypermedia as the subclass of REST APIs that send and accept machine-interpretable representations using semantic media types (possibly in addition to others). Assuming a client that understands the generic base type (such as Turtle, RDFa, or RDF/interpretation
of course doesn’t mean that autonomous agents suddenly obtain capabilities comparable to those of humans, it does lead to the following:
Semantic media types can help realize Postel’s law: be conservative in what you send, be liberal in what you accept
.
- Representations can describe resources at any desired level of detail. In contrast to structure-based formats such as JSON, where consumers expect specific keys and values organized in a rather strict way, RDF is entirely resource-centric and triples can detail any (sub-)resource as desired. Clients and servers can simply ignore triples irrelevant to their current task.
-
Servers can allow their clients a flexible choice of vocabulary, as reasoning enables inferring certain properties from others. For instance, clients could indicate a resource’s label with
rdfs:label,dc:title,foaf:nameor others; the server can infer equivalence. To facilitate interpretation, both parties could express facts in several vocabularies, as unneeded triples can be ignored anyway. -
Agents that receive instructions in a semantic way, like in the process detailed in Chapter 4, can relate a server’s response to the query without needing application domain knowledge. For instance, if the query requests a
dbpedia-owl:Imagewith certain properties, the agent can verify whether the server’s response meets the criteria, without requiring a built-in notion of images.
Semantic hypermedia thus enables a higher autonomy of clients.
The differences between various non-semantic and semantic media types are independent of a specific representation design.
We will contrast the approaches through an example. Suppose an API offers entity lookup: given properties about a topic, it tries to find a unique identifier. We could create a specific media type for this, based on JSON, that we name application/vnd.rv.entities+json. An example query document could be represented as:
{ "entities": [
    { "name": "Pete Townshend", "type": "person" },
    { "name": "Terry Riley",    "type": "person" } ] }
The server could then represent a response as:
{ "entities": [
    { "name": "Pete Townshend", "id": "dbpedia:Pete_Townshend" },
    { "name": "Terry Riley",    "id": "freebase:07qf7" } ] }
To understand these fragments, clients need to know the meaning of entities, name, type, and id, as well as their structure. Furthermore, this knowledge is not transferable to other media types, which might even have different interpretations for those fields.
Compare this to a possible RDF representation of the query:
_:p1 a foaf:Person; rdfs:label "Pete Townshend".
_:p2 a foaf:Person; dc:title "Terry Riley";
     schema:birthDate "1935-06-24"^^xsd:date.
Note how the knowledge needed for interpretation is independent of this specific media type: rdfs:label and schema:birthDate have a universal meaning. Furthermore, if the meaning would be unknown, a client can look it up through its property URL and relate it to known concepts.
To add new properties in structure-based formats, the field name would have to be agreed on first.
Note also how different properties indicate labels, and how an extra property birthDate was supplied to allow disambiguation. Maybe the server doesn’t support it at the moment, but when it does, the property will be recognized. The server could respond with:
dbpedia:Pete_Townshend rdfs:label "Pete Townshend".
freebase:07qf7 rdfs:label "Terry Riley";
               dc:title   "Terry Riley".
Again, this can be interpreted by any client that can parse Turtle. Note that the server can specify the label in multiple vocabularies.
The JSON-LD media type provides evolvable JSON representations by giving them RDF semantics [12].
This illustrates how semantic formats make representations self-descriptive, removing the need for specific media types. Conveniently, the transition to semantic hypermedia does not have to be disruptive: content-negotiation allows the client to request either a JSON- or an RDF-based representation of the resource.
Non-hypermedia formats can still allow hypermedia-driven navigation through Link headers in the HTTP response [13].
The remaining question is how clients can construct representations in absence of the rigid structure imposed by a specific media type. While RESTdesc explains the functionality of an API by relating its preconditions to its postconditions, it purposely does not detail the representation of the exchanged messages. This allows clients to engage in content negotiation at runtime and to deal with non-textual content such as images and videos. In the previous example, RESTdesc could explain that properties of entities lead to identifiers of those entities, but it would not detail the format of either message. While a client can interpret a server’s response automatically because of the embedded semantics, the RESTdesc description doesn’t detail how the entities should be sent to the server. In this example, the RDF format is so simple it could be guessed
: it simply describes the available entity properties. In the general case, more possibilities exist and we need to understand the server’s preferences without a specific media type.
One solution is to explicitly describe the expected request and response triple patterns [14]. These techniques often relate to lifting and lowering, the transformation between non-semantic and semantic representations [15]. Unfortunately, pattern descriptions restrict the possibilities not enough on the one hand, such as when only certain value ranges are allowed, and too much on the other hand, since they block the flexibility that RDF brings. On the positive side, they can be considered a machine-interpretable equivalent of media type definitions, which the client can discover at runtime.
Making an API machine-friendly means adjusting its affordance accordingly.
However, we believe that a hypermedia strategy is the appropriate solution here. Similar to how human-targeted representation formats offer forms to structure input (such as HTML’s <form> element), hypermedia representations for machine clients should provide the controls that afford the desired actions. The RDF forms initiative [16] was a first attempt to achieve this in RDF, yet further developments are necessary [17]. The Hydra vocabulary [18] seems promising in this regard. An alternative approach is to semantically annotate HTML input fields, so machine clients can understand their purpose. Such techniques for hypermedia forms make the interaction fully happen in-band, similar to the mechanism for links. As a result, they integrate seamlessly into the hypermedia-driven process of Chapter 4.
An error response should also obey a client’s media type preferences through content negotiation, so the client can act upon it.
As a final remark, we shouldn’t forget that error responses also require machine interpretation. Recently, a generic method to detail the cause of HTTP error responses in JSON [19] was proposed. Again, using a semantic media type for this would allow clients to interpret errors without any prior understanding. An interpretation of an error’s cause could help in finding an alternative strategy.
Discovering semantic resources
Centralized indexes seemingly contradict the nature of distributed systems, but they remain the quickest method. Future advances in distributed search techniques might change this.
For agents to become truly autonomous, they should not only know how to browse APIs, but also how to find them. On a distributed system such as the Web, efficient discovery relies on indexes. In the beginning days of the Web, a manual list of servers was maintained, which gradually became obsolete through the advent of keyword-based search engines [20]. Much of our daily online activities involve search engines: to find starting points for a task and, if the affordance toward the next desired step is missing, to find that step as well.
Business plans for indexes targeting machine clients require special thought, as machines cannot generate revenue through watching advertisements.
Machine clients currently have only limited access to search. One could think this is not necessary because Linked Data leads to related resources, but the unidirectionality of Web linking prevents many interesting lookups. For instance, photos of a certain person are often annotated with an identifier of that person, but it’s highly unlikely that the description of a person will link to all her photos. Hence, if an agent needs to find all those photos, an identifier of the person will not directly yield the needed information. We need the equivalent of a search engine, but with a focus on machine clients. Sindice [21] is an index of machine-interpretable data on the Web that crawls semantic formats such as RDF and semantic annotations in HTML documents. It allows finding documents about concepts using their URI or property values through a Web API or a SPARQL endpoint. However, ranking, the key feature of search engines to display the most relevant results first, is currently difficult with triples. Consequently, finding the relevant information to solve a certain task often involves trial and error.
In many cases, full autonomy isn’t required. Agents can simply receive access to a large API description collection, since selection of APIs happens fast.
Furthermore, Sindice only indexes static content. To search for Web APIs that offer a certain functionality, we need more advanced discovery mechanisms. Many solutions for service discovery have been developed [22, 23], but none of them were deemed the definitive answer. Given the performance of RESTdesc matching, we believe that a repository with RESTdesc descriptions could give fast replies to queries for a certain functionality. However, considering more complex matching operations that take vocabulary differences into account can require significantly more server resources. Perhaps functionality could be discovered in an indirect way by providing URIs of related concepts, similar to keyword-based search. An agent could then retrieve semantically related API descriptions and evaluate whether they match a task. Once a starting point has been given, the client could discover an API in a hypermedia-driven process, like the way developers browse an API’s documentation. Yet, the discovery aspect of autonomous agents clearly still needs intensive research.
Toward serendipitous Web applications
When automated clients have access to serendipitous interactions on the Web, they themselves become providers of serendipity: users can ask to achieve a certain goal and a client will do so, as if it was programmed for this specific task by chance. We define serendipitous Web applications as those applications that can use the Web in ways they were not explicitly designed for. Although slightly utopian today, we advance toward a Web on which machine clients can perform increasingly complex tasks. We consider autonomous agents, semantics-driven applications, and client-side querying.
Autonomous agents
David Martin, one of the driving forces behind Siri, was also a co-author of the OWL-S specification, so some of Siri’s roots lie in the Semantic Web.
Much of the thinking that underpins this work was inspired by the Semantic Web vision of agents [24]. Even acknowledging the fact that the authors were outlining an idea and not an actual plan, the achieved successes so far have only laid the bare foundations. Commercial personal digital assistants such as Apple’s Siri seem to come closer to the envisioned agents than the current research of the scientific Semantic Web community. However, Siri isn’t an agent in that sense, because it can only perform actions it has been preprogrammed for (admittedly in an intuitive and personalized way). In particular, it cannot interact with Web APIs it hasn’t been designed for. We thus wouldn’t call Siri a serendipitous application.
Autonomous agents can satisfy a goal on the Web, for instance through the hypermedia-driven process we introduced. The challenge is to make this work outside of controlled environments, as agents do depend on semantic descriptions, which are not commonly available.
What is it then that Semantic Web agents can do, and what does the technology introduced in the previous chapters add to that? The main goal is autonomy: having an agent perform a task without (or with minimal) assistance. As we’ve outlined, this includes discovery of data and functionality, an interpretation thereof, composition of a plan, the execution of its steps, and reporting back to the user. Thanks to the Web, agents can rely on knowledge and services from many different providers; the challenge is to do this intelligently. Hypermedia-driven execution is an important part of the solution, so agents don’t need to know the steps of any interaction beforehand. Instead, they can follow the controls provided by servers to advance the application state. In case a representation doesn’t contain the desired controls, they can be added through distributed affordance.
As long as agents cannot fully interpret natural language, they need machine-readable representations of the content and functionality offered by Web APIs. These also allow agents to plan in advance. This semantic gap remains the most pressing issue, as it prevents users from interacting with autonomous agents in a more fluent way. The silver bullet is to allow the specification of tasks in natural language.
Semantics-driven applications
Unlike Web 2.0 mashups, which work against a fixed set of data sources, Linked Data applications operate on top of an unbound, global data space.
[25]
Linked Data is supposed to make the development of data mashups easier, because it can be flexibly shaped into different formats. However, applications developed with Linked Data often remain confined to the silos they were created in [26]. Although Linked Data should enable reuse in theory, few applications can readily switch to another dataset. For instance, it would be common practice to develop a new sightseeing application for every city—
In practice, there might be commercial reasons to develop multiple applications. From the software engineering viewpoint, it isn’t a necessity.
Where did we go wrong? An explanation can be found in the way Linked Data applications are currently developed. We notice that, despite adopting RDF’s triple model, data is still treated the same way as with more rigid models. Developers make assumptions about what properties will be used, which values will be there, and how concepts can be identified. These assumptions have proven unportable across different datasets, which are structured according to slightly different design decisions. This illustrates how applications are primarily built in a data-driven way that highly depends on the data’s structure, even though the data model possesses more flexibility. We should evolve toward a semantics-driven way, in which developers bind the application to the semantics rather than to the data.
We need to shift our perspective to realize such semantics-driven applications. While the current approach is to build applications on top of datasets, we should create applications to which different data streams can be connected. In other words, a specific dataset shouldn’t influence the internal design of the application, but the application should shape incoming data streams instead. Concretely, a specific application must implement a certain service, and users should be allowed to choose the dataset on which the application provides that service—
Binding to data semantics will lead to higher development costs for a single application, yet only one application is needed for many different scenarios.
As different datasets are often expressed in different ways and varying levels of granularity, we need to put mechanisms in place to deal with this in a uniform way. By not querying the data directly but asking a reasoner to infer the desired triples, differences between ontologies can be bridged. This requires dereferencing the URIs of the used properties to supply input for the reasoner, which then relates them to properties that are known to the application. Therefore, the application only needs to be programmed against a specific set of properties, as the semantics in the dataset allow a reasoner to shape the data in the expected format.
Client-side querying
The load of HTTP servers is far more predictable, as the server is responsible for resource partitioning. SPARQL, in contrast, allows clients to send arbitrarily complex requests [27].
The major challenge when consuming large quantities of data is to find those specific elements you are looking for. The SPARQL protocol [28] allows to execute SPARQL queries [29] on RDF data over the Web. The current principle is that a client sends a query to a server, which then executes this query over its internal RDF store. However, the scalability of this approach quickly becomes problematic. With public SPARQL endpoints, the server is not in control of the number of requests and their complexity. As a result, the availability of public SPARQL endpoints is notoriously problematic [30].
We ran tests with complex queries, which, in medium to large numbers, quickly bring down SPARQL servers. Most of these queries could be executed client-side within a few seconds [31].
Serendipity can only happen if the client is sufficiently intelligent. I believe that, in order to develop intelligent clients, we should refrain from building intelligent servers. The SPARQL vision of having a single endpoint that will solve any query might work in closed environments, but not on a Web scale. Instead, we should offer clients the affordance to solve queries themselves. The idea of Linked Data Fragments [31] is to partition a data source into chunks of Linked Data, such that client-side querying becomes possible. While this necessitates more data transfer, each fragment is cacheable and reusable across multiple clients. Partitionings are designed to require only minimal server processing for a fragment. The conceptual difference is shown below.
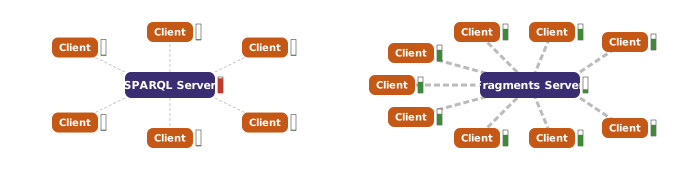
Note how, when using Linked Data Fragments, the clients perform the actual computation, whereas the server merely supplies the data. As a result, servers can handle many more clients because the complexity of each request is controlled, and the number of computing units increases linearly with the number of clients.
Additionally, client-side query execution facilitates querying from distributed data sources. A client then simply needs to combine fragments from different servers—
A concrete partitioning that minimizes server effort while still enabling powerful queries consists of fragments for all triple patterns ?s ?p ?o of a dataset, wherein each component can be variable or fixed. In addition, the server should provide metadata such as counts, and controls such as links to other triples. A query for a basic graph pattern, consisting of many such triples, can then be solved at the client side by iteratively querying for those subpatterns with the lowest member count [31]. This enables dynamic, Web-scale querying.
By combining the strengths of hypermedia and semantic technologies in a pragmatic way, we can develop a new generation of Web applications that serendipitously reach goals they were not specifically programmed for. Such applications deliver the flexibility promised by Linked Data, if we are willing to take the additional effort to bind our application not to the data itself but to its semantics. In addition to functional descriptions, semantic hypermedia types can play a fundamental role in the autonomous consumption of APIs by serendipitous applications. This paves the way for autonomous agents, semantics-driven applications, and scalable client-side querying on the Web.
References
- [1]
- Fielding, R.T. (2007), “Re: ‘I finally get REST. Wow.’”, The REST architectural style list, 8 May, available at: http://tech.groups.yahoo.com/
group/ .rest-discuss/ message/ 8343 - [2]
- Vinoski, S. (2008), “Serendipitous Reuse”, Internet Computing, IEEE, Vol. 12 No. 1, pp. 84–87, available at: https://doi.org/
10.1109/ .MIC.2008.20 - [3]
- Bush, V. (1945), “As we may think”, The Atlantic Monthly, Vol. 176 No. 1, pp. 101–108, available at: http://www.theatlantic.com/
magazine/ .archive/ 1945/ 07/ as-we-may-think/ 303881/ - [4]
- Lanthaler, M. (2013), “Creating 3rd generation Web APIs with Hydra”, in Proceedings of the 22nd International Conference on World Wide Web – Companion, pp. 35–38, available at: http://www.markus-lanthaler.com/
research/ .creating-3rd-generation-web-apis-with-hydra.pdf - [5]
- Webber, J., Parastatidis, S. and Robinson, I. (2010), REST in Practice, O’Reilly.
- [6]
- Fielding, R.T. (2008), “REST APIs must be hypertext-driven”, Untangled – Musings of Roy T. Fielding, October, available at: http://roy.gbiv.com/
untangled/ .2008/ rest-apis-must-be-hypertext-driven - [7]
- Richardson, L., Amundsen, M. and Ruby, S. (2013), RESTful Web APIs, O’Reilly, available at: http://shop.oreilly.com/
product/ .0636920028468.do - [8]
- Hansen, T. and Melnikov, A. (2013), Additional Media Type Structured Syntax Suffixes, Request For Comments No. 6839, Internet Engineering Task Force, available at: http://tools.ietf.org/
html/ .rfc6839 - [9]
- Freed, N., Klensin, J. and Postel, J. (1996), Multipurpose Internet Mail Extensions (MIME) Part Four: Registration Procedure, Request For Comments No. 2048, Internet Engineering Task Force, available at: http://tools.ietf.org/
html/ .rfc2048 - [10]
- Fielding, R.T. (2000), Architectural Styles and the Design of Network-Based Software Architectures, PhD thesis, University of California, available at: http://www.ics.uci.edu/~fielding/
pubs/ .dissertation/ top.htm - [11]
- Berners-Lee, T. (2006), “Linked Data”, July, available at: http://www.w3.org/
DesignIssues/ .LinkedData.html - [12]
- Lanthaler, M. and Gütl, C. (2012), “On using JSON-LD to create evolvable RESTful services”, in Proceedings of the Third International Workshop on RESTful Design, ACM, pp. 25–32, available at: http://www.markus-lanthaler.com/
research/ .on-using-json-ld-to-create-evolvable-restful-services.pdf - [13]
- Nottingham, M. (2010), Web Linking, Request For Comments No. 5988, Internet Engineering Task Force, available at: http://tools.ietf.org/
html/ .rfc5988 - [14]
- Krummenacher, R., Norton, B. and Marte, A. (2010), “Towards Linked Open Services and Processes”, in Future Internet Symposium, Vol. 6369, Lecture Notes in Computer Science, Springer, pp. 68–77, available at: https://doi.org/
10.1007/ .978-3-642-15877-3_8 - [15]
- Kopecký, J., Roman, D., Moran, M. and Fensel, D. (2006), “Semantic Web Services Grounding”, in Proceedings of the International Conference on Internet and Web Applications and Services, pp. 127–127, available at: https://doi.org/
10.1109/ .AICT-ICIW.2006.165 - [16]
- Baker, M. (2003), “RDF Forms”, May, available at: http://www.markbaker.ca/
2003/ .05/ RDF-Forms/ - [17]
- Kjernsmo, K. (2012), “The necessity of hypermedia RDF and an approach to achieve it”, in Proceedings of the Workshop on Linked APIs for the Semantic Web, available at: http://lapis2012.linkedservices.org/
papers/ .1.pdf - [18]
- Lanthaler, M. and Gütl, C. (2013), “Hydra: A Vocabulary for Hypermedia-Driven Web APIs”, in Proceedings of the 6th Workshop on Linked Data on the Web, available at: http://ceur-ws.org/
Vol-996/ .papers/ ldow2013-paper-03.pdf - [19]
- Nottingham, M. (2013), “Indicating Problems in HTTP APIs”, 15 May, available at: http://www.mnot.net/
blog/ .2013/ 05/ 15/ http_problem - [20]
- Berners-Lee, T. (1999), Weaving the Web: The Original Design and Ultimate Destiny of the World Wide Web by Its Inventor, HarperCollins Publishers.
- [21]
- Tummarello, G., Delbru, R. and Oren, E. (2007), “Sindice.com: Weaving the Open Linked Data”, in Proceedings of the 6th International Semantic Web Conference, Springer, pp. 552–565, available at: http://dl.acm.org/
citation.cfm?id=1785162.1785203 . - [22]
- Bellwood, T. (Ed.). (2002), UDDI Version 2.04 API Specification, available at: http://uddi.org/
pubs/ .ProgrammersAPI-V2.04-Published-20020719.htm - [23]
- Klusch, M., Fries, B. and Sycara, K. (2006), “Automated Semantic Web Service Discovery with OWLS-MX”, in Proceedings of the 5th International Joint Conference on Autonomous Agents and Multiagent Systems, ACM, pp. 915–922, available at: https://doi.org/
10.1145/ .1160633.1160796 - [24]
- Berners-Lee, T., Hendler, J. and Lassila, O. (2001), “The Semantic Web”, Scientific American, Vol. 284 No. 5, pp. 34–43, available at: http://www.scientificamerican.com/
article.cfm?id=the-semantic-web . - [25]
- Bizer, C., Heath, T. and Berners-Lee, T. (2009), “Linked Data – The Story So Far”, International Journal on Semantic Web and Information Systems, Vol. 5 No. 3, pp. 1–22, available at: http://tomheath.com/
papers/ .bizer-heath-berners-lee-ijswis-linked-data.pdf - [26]
- Dimou, A., Colpaert, P., Troncy, R., Mannens, E. and Van de Walle, R. (2013), “Cataloguing Open Data Applications using Semantic Web Technologies”, in EU Networking Session at the 10th Extended Semantic Web Conference.
- [27]
- Verborgh, R. (2014), “Can I SPARQL your endpoint?”, 30 September, available at: http://ruben.verborgh.org/
blog/ .2013/ 09/ 30/ can-i-sparql-your-endpoint/ - [28]
- Feigenbaum, L., Williams, G.T., Clark, K.G. and Torres, E. (2013), SPARQL 1.1 Protocol, Recommendation, World Wide Web Consortium, available at: http://www.w3.org/
TR/ .sparql11-protocol/ - [29]
- Harris, S. and Seaborne, A. (2013), SPARQL 1.1 Query Language, Recommendation, World Wide Web Consortium, available at: http://www.w3.org/
TR/ .sparql11-query/ - [30]
- Buil-Aranda, C., Hogan, A., Umbrich, J. and Vandenbussche, P.-Y. (2013), “SPARQL Web-Querying Infrastructure: Ready for Action?”, in Proceedings of the 12th International Semantic Web Conference, available at: http://link.springer.com/
chapter/ .10.1007/ 978-3-642-41338-4_18 - [31]
- Verborgh, R., Colpaert, P., Coppens, S., Vander Sande, M., Mannens, E. and Van de Walle, R. (2014), “Web-Scale Querying through Linked Data Fragments”.