
Chapter 5 – Proof
I don’t need to fight
To prove I’m right
I don’t need to be forgiven The Who, Baba O’Riley (1971)
Proofs justify how we arrived at a conclusion given a set of facts and rules that we’re allowed to apply. On the Semantic Web, a proof lets a machine explain precisely how it obtained a certain result. Although usually reserved for static data, in this chapter, proofs will play a crucial role in the dynamic world of Web APIs. With some creativity, they can guarantee the correctness of a composition of several Web APIs before its execution, and even serve as an efficient method to automatically create such compositions.
Each individual argument needs to be verifiable, as contradicting facts lead to the principle of explosion: an inconsistency allows to conclude anything.
The ability to prove that a conclusion is correct has become one of the foundations of science. A proof justifies a statement by decomposing it into more elementary pieces, which may only be combined using a strictly constrained methodology. Those pieces can in turn be proven, until we arrive at fundamental elements that we cannot decompose and have chosen to accept as truth. The mechanisms of proof allow us to discover knowledge derived from the truth—
In a world where actions will be undertaken autonomously by machines, an important question is whether these actions and their results represent the intentions of the person who instructed those machines. Therefore, it shouldn’t come as a surprise that the notion of proof
was already present in the initial Semantic Web vision [1]. Results obtained by machines can be trusted when accompanied by an independently verifiable, machine-readable proof document. Such proofs can then be exchanged by different parties [2] and verified by dedicated proof checkers.
Automated agents require an even higher trust level than most Web applications, because people are no longer directly in control of decisions.
Additionally, trust is an important aspect. If a proof uses a certain piece of data as justification, then you need to be able to decide whether you can rely on its source. Together with digital signatures that allow to verify the authenticity of the information, trust records ensure that the foundations of the proof are valid [1]. Certainly in an environment where anyone can say anything about anything
[3], we need to be selective as to what information we let our conclusions be built upon.
The apparent shortage of Linked Rules
is rather unfortunate, since a main N3Logic goal was precisely to share information that requires more expressivity than regular RDF [4].
Unfortunately, proof on today’s Web is still at an early stage. In Chapter 3, we discussed Linked Data as a pragmatic view on the Semantic Web—
As we would expect, N3 proofs generated by one reasoner can be parsed and interpreted by another. Interoperability is as crucial as with data.
On the bright side, many current N3 reasoners provide support to prove the conclusions drawn from triples and rules. As part of the Semantic Web Application Platform [5], the cwm reasoner and an ontology with elementary components like Proof and Inference [6] were created. The ontology is usually referred to by the r prefix and the corresponding URL http://www.w3.org/
In this chapter, we will first discuss the essential components of N3 proofs with static data and rules. Next, we will incorporate dynamic information in those proofs by using RESTdesc descriptions of Web APIs. This then leads to the question of how we can be sure that a given composition of Web APIs realizes desired functionality, and how such compositions can be created automatically. Finally, we’ll explain the role of proofs in the hypermedia-driven execution process of autonomous agents.
Understanding proofs
Ancient syllogisms have had a profound influence on deductive reasoning.
To understand how N3 reasoners generate proofs and how these proofs are structured, we will study the N3 proof of a classical syllogism. It expresses perhaps the most famous example of inference:
Socrates is a man, and all men are mortal.
Therefore, Socrates is mortal.
This translates into predicate logic as follows:
Storing data and rules as separate resources allows independent reuse.
Our goal is to obtain this conclusion from an N3 reasoner. To that end, we first have to represent the initial knowledge as RDF. The triple below has been found at http://dbpedia.org/
dbpedia:Socrates a dbpedia-owl:Person.
The implication can be represented as follows in an N3 document:
{ ?person a dbpedia-owl:Person. }
=>
{ ?person a dbpedia-owl:Mortal. }.
We could present both resources to an N3 reasoner and demand to derive all possible statements that can be entailed. However, this might not always be practical: the number of entailed triples can potentially be enormous, even with a moderate number of rules, and not all of those triples are relevant to solve the given question. In the worst case, rules can trigger recursively and lead to an infinite stream of triples, which can of course never be generated.
Any rule in which the antecedent and consequent are the same might seem a strange tautology. After all, always holds, so why include it then? The answer is that filter rules are not knowledge rules; they instruct a reasoner to find the graph and to derive a graph , which could (but doesn’t need to) be identical to .
Instead, we’ll ask a specific query: all triples that have Socrates as the subject. This is the graph pattern
Most N3 reasoners have a specific query mechanism called filter rules, which are N3 rules used in a similar way to SPARQL dbpedia:Socrates ?p ?o.CONSTRUCT queries. A filter rule’s antecedent instructs the reasoner to find all matching patterns, which are then shaped according to the rule’s consequent. Since we are interested in Socrates
triples, and we want to retrieve them exactly as they are, our filter rule becomes:
{ dbpedia:Socrates ?p ?o. }
=>
{ dbpedia:Socrates ?p ?o. }.
The reasoner is asked to execute this query on the given N3 documents.
Figure 3 lists an example proof generated by the EYE reasoner [7] in response to our input and query, using the following command:
eye socrates.ttl mortal.n3 --query query.n3
Query results can contain both pre-existing and entailed triples.
The query execution results in the following triples:
dbpedia:Socrates a dbpedia-owl:Person.
dbpedia:Socrates a dbpedia-owl:Mortal.
We will now go through the proof to understand how the reasoner arrived at this conclusion, thus starting from the result and heading toward the initial facts. At the highest level, a proof consists of a Proof entity, which is a Conjunction of different components. In this case, those components are #lemma1 and #lemma2. The proof gives the two Socrates triples, the derivation of which is detailed by these Lemmata 1 and 2, which in turn have their own justification. There are two possible lemma types: Inference and Extraction.
For consistency reasons, the filter rule will always be instantiated explicitly, even if it is a pass-through rule that simply returns the same, as in this case. The reasoner is obliged to instantiate the filter rule before arriving at the final conclusion; its usage can in fact be considered the reasoner’s goal.
Lemma 1 is an inference that results in the fact that Socrates is a man. It might seem surprising to see this fact is the result of an inference rather than a simple extraction, as it was also present in the input files. However, the rule used for this lemma is the special filter rule (Lemma 4), which was instantiated with the triple itself (Lemma 3), leading indeed to this conclusion. In other words, Lemmata 3 and 4 detail the origin of the knowledge (Socrates is a man
) and the filter rule (find a triple about Socrates and return it
), whereas Lemma 1 details the instantiation of this rule with the knowledge using rule and evidence predicates. Extractions such as #lemma3 and #lemma4 don’t require further proving, as they directly point to the source that must be parsed to obtain the triple or rule.
Interestingly, proving the main
inference is only a small part of the whole.
Lemma 2, the other component of the main proof, also shows an application of the filter rule, as indicated by its rule property. This lemma results in the fact that Socrates is a mortal. However, the evidence isn’t an extraction this time, but another inference detailed in Lemma 5. This lemma then derives Socrates’ mortality by applying the if human, then mortal
rule (Lemma 6) on the fact that Socrates is human (Lemma 3). As the binding details, the rule is instantiated by replacing the variable ?person by dbpedia:Socrates:
{ dbpedia:Socrates a dbpedia-owl:Person. }
=>
{ dbpedia:Socrates a dbpedia-owl:Mortal. }.
This leads to the conclusion of Lemma 5, which was picked up by the filter rule in Lemma 2 and finally propagated to the main proof.
@prefix dbpedia: <http://dbpedia.org/resource/>.
@prefix dbpedia-owl: <http://dbpedia.org/ontology/>.
@prefix var: <var#>.
@prefix r: <http://www.w3.org/2000/10/swap/reason#>.
@prefix n3: <http://www.w3.org/2004/06/rei#>.

<#proof> a r:Proof, r:Conjunction;
  r:component <#lemma1>, <#lemma2>;
  r:gives {
    dbpedia:Socrates a dbpedia-owl:Person.
    dbpedia:Socrates a dbpedia-owl:Mortal.
  }.

<#lemma1> a r:Inference; r:gives { dbpedia:Socrates a dbpedia-owl:Person };
  r:evidence (<#lemma3>);
  r:binding [ r:variable [ n3:uri "var#p" ];
              r:boundTo  [ n3:uri "http://www.w3.org/1999/02/22-rdf-syntax-ns#type" ]];
  r:binding [ r:variable [ n3:uri "var#o" ];
              r:boundTo  [ n3:uri "http://dbpedia.org/ontology/Person" ]];
  r:rule <#lemma4>.

<#lemma2> a r:Inference; r:gives { dbpedia:Socrates a dbpedia-owl:Mortal };
  r:evidence (<#lemma5>);
  r:binding [ r:variable [ n3:uri "var#p" ];
              r:boundTo  [ n3:uri "http://www.w3.org/1999/02/22-rdf-syntax-ns#type" ]];
  r:binding [ r:variable [ n3:uri "var#o" ];
              r:boundTo  [ n3:uri "http://dbpedia.org/ontology/Mortal" ]];
  r:rule <#lemma4>.

<#lemma3> a r:Extraction; r:gives { dbpedia:Socrates a dbpedia-owl:Person };
  r:because [ a r:Parsing; r:source <socrates.ttl> ].

<#lemma4> a r:Extraction; r:gives { @forAll var:p, var:o.
            { dbpedia:Socrates var:p var:o } => { dbpedia:Socrates var:p var:o }};
  r:because [ a r:Parsing; r:source <query.n3> ].

<#lemma5> a r:Inference; r:gives { dbpedia:Socrates a dbpedia-owl:Mortal };
  r:evidence (<#lemma3>);
  r:binding [ r:variable [ n3:uri "var#person" ];
              r:boundTo  [ n3:uri "http://dbpedia.org/resource/Socrates" ]];
  r:rule <#lemma6>.

<#lemma6> a r:Extraction; r:gives { @forAll var:person.
            { var:person a dbpedia-owl:Person } => { var:person a dbpedia-owl:Mortal }};
  r:because [ a r:Parsing; r:source <mortal.n3> ].
Figure 3: A proof is a conjunction of components, recursively constructed out of inferences and extractions. This proof indicates that, if all men are mortal and Socrates is a man, then Socrates is mortal.
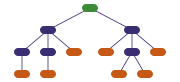
Each proof is a graph that starts from the conclusion, going through inferences to arrive at trusted facts.
From this example, it is apparent that N3Logic proofs, just like mathematical proofs, have a recursive structure. Each derived triple must be justified by a lemma, the assumptions of which have to be justified in turn, until we arrive at the parsing of input files, which are the axioms. At that level, acceptance becomes a matter of trust, unless the input files themselves are accompanied by a proof. Another observation is that proofs have a backward flow: they start from the conclusion, which is gradually decomposed into elementary parts. This might lead to confusion at first, since we will encounter results before we learn how they are derived. Yet, it fits the central philosophy of tracing back each fact to a derivation from other verifiable facts, until we arrive at the source.
Jim Hendler provides an example [2] wherein a server states an agent is in debt. Reluctant to transfer the money without a cause, the agent asks for proof. The server then justifies its demand with evidence of some unpaid purchase. Now convinced, the agent sends the sum due.
In this context, the proof can be interpreted as a dialog. If one agent claims that Socrates is a mortal, another agent can ask why. In response, the first agent will say this is the result of applying a specific rule on the fact that Socrates is a human. Still unsatisfied, the other agent demands more details, upon which the first explains this fact was obtained from socrates.ttl with the rule extracted from mortal.n3. The other can then choose to ask the same questions to the data sources of these files, where it would perhaps learn that the contents of socrates.ttl were taken from DBpedia. The interrogation continues until the agent finds sources it trusts (or not, in which case it rejects the proof result because of unsure premises).
The proofs we have discussed so far employ pre-existing facts to justify a certain assertion. In contrast, we want to verify whether the execution of a series of Web API calls—
We’re again safeguarded by RESTdesc’s choice to place the HTTP request as an existential in the conclusion: a proof will state a chain of requests matching the goal exists, without claiming success for all executions.
Since RESTdesc descriptions are expressed as N3 rules, they can also serve as inferences in proofs. What distinguishes RESTdesc rules from others is that they describe the expected results of Web API calls, which are not necessarily executed. So under the assumption that the employed RESTdesc descriptions accurately capture the result that will occur in reality, proofs with RESTdesc rules can be interpreted as Web API compositions that reach a certain goal. In addition to indicating if a goal can be fulfilled, the proof will explain how, by detailing a possible chain of HTTP requests.
Automatically generating compositions
Instead of applying proofs to verify the derivation of facts from static knowledge, we will now discuss a proof that shows how a goal can be achieved using Web API calls. Suppose an agent has access to the local image lena.jpg as part of its background knowledge:
<lena.jpg> a dbpedia:Image.
The goal set by the user is to obtain a thumbnail of that specific image:
{ <lena.jpg> dbpedia-owl:thumbnail ?result. }
=>
{ <lena.jpg> dbpedia-owl:thumbnail ?result. }.
Descriptions can be given explicitly or discovered automatically, as we will discuss in Chapter 7.
To solve this problem, it has several Web API descriptions at its disposition, including the ones we have discussed in the previous chapter. The description below explains that smallThumbnail links lead to an 80px-high thumbnail:
{ ?image ex:smallThumbnail ?thumbnail. }
=>
{
  _:request http:methodName "GET";
            http:requestURI ?thumbnail;
            http:resp [ http:body ?thumbnail ].
  ?image dbpedia-owl:thumbnail ?thumbnail.
  ?thumbnail a dbpedia:Image;
             dbpedia-owl:height 80.0.
}.
The following description captures the fact that images uploaded to the /images/ resource receive comments and smallThumbnail links:
Some details have been omitted from the upload description to simplify the proof slightly. Yet, using the exact description as in Chapter 4 would yield analogous results.
{ ?image a dbpedia:Image.  }
=>
{
  _:request http:methodName "POST";
            http:requestURI "/images/";
            http:body ?image;
            http:resp [ http:body ?image ].
  ?image ex:comments _:comments;
         ex:smallThumbnail _:thumb.
}.
In practice, many more descriptions will be available; it is precisely the task of the reasoner generating the proof to select the relevant ones.
Parsing details were not listed; Lemmata 4 to 7 of the proof correspond to the respective snippets above.
Figure 4 shows the proof that was obtained by sending the background knowledge and several descriptions to a reasoner with the given query. As expected, its structure is similar to that of Figure 3: one main proof entity, recursively decomposed into inferences and extractions. The difference lies in the usage of RESTdesc descriptions to perform inferences. Since RESTdesc expresses functionality as regular N3 rules, reasoners do not need additional knowledge to incorporate them in proofs. At the same time, all the instantiated descriptions retain their additional operational meaning.
While proofs are constructed from the conclusion toward the initial assumptions, Web API executions start from an initial state to finally arrive at a goal. Therefore, in this discussion, we will follow the proof in the reverse direction, in order to highlight the connection to Web APIs. Since Lemmata 4 to 7 are merely extractions obtained through parsing, we will skip to the first inference that uses them.
At first sight, more existentials seem to appear in the proof than in the description. This is not the case: even though the resp triple is written in [] notation, it remains a blank node, which thus needs a new identifier.
Lemma 3 details the instantiation of the RESTdesc description for image uploading (Lemma 7). The knowledge that lena.jpg is an image (Lemma 4) satisfies that description’s precondition, so it is triggered. Note how the image variable is bound to lena.jpg, whereas all existentially quantified variables are instantiated with newly created blank nodes, as can be seen by the Existential type. Here, the parametrized request in the RESTdesc rule’s consequent has been instantiated to a POST request to /images/ with a request body of lena.jpg. All necessary information to construct this request is thus in place. Even though the outcome of the request is unknown at this stage, the description stated there would be comments and smallThumbnail links. As their exact targets cannot be determined yet, they’re represented by the new blank nodes _:sk2 and _:sk3.
The usage of blank nodes in RESTdesc rules serves as a way to track values throughout a proof.
Lemma 2 continues from the obtained result that lena.jpg has a smallThumbnail link to _:sk3, instantiating this in the corresponding RESTdesc API description (Lemma 6). The actual thumbnail URL is undetermined, which is reflected in the incompleteness of the resulting API call—GET request to _:sk3 that leads to the thumbnail. While its actual value is still undetermined, _:sk3 is not unspecified: it refers to the target of the smallThumbnail link that will be obtained through the POST request in Lemma 3. The hypermedia links and their semantics propagate through the proof as blank nodes, substitutes for concrete values that will be determined during the execution.
Finally, Lemma 1 is the obligatory instantiation of the filter rule that represents the agent’s goal (Lemma 5). It takes the conclusion of Lemma 2—thumbnail—and finds _:sk3 as the needed result. Lemma 1 is thereby sufficient to conclude the proof.
<#proof> a r:Proof, r:Conjunction;
  r:component <#lemma1>;
  r:gives { <lena.jpg> dbpedia-owl:thumbnail _:sk3. }.

<#lemma1> a r:Inference;
  r:gives { <lena.jpg> dbpedia-owl:thumbnail _:sk3. };
  r:evidence (<#lemma2>);
  r:binding [ r:variable [ n3:uri "var#result"];
              r:boundTo  [ a r:Existential; n3:nodeId "_:sk3"]];
  r:rule <#lemma5>. # extracted by parsing agent_goal.n3

<#lemma2> a r:Inference;
  r:gives { _:sk4 http:methodName "GET".  _:sk4 http:requestURI _:sk3.
            _:sk4 http:resp _:sk5.        _:sk5 http:body _:sk3.
            <lena.jpg> dbpedia-owl:thumbnail _:sk3.
            _:sk3 a dbpedia:Image.        _:sk3 dbpedia-owl:height 80.0. };
  r:evidence (<#lemma3>);
  r:binding [ r:variable [ n3:uri "var#image"];
              r:boundTo  [ n3:uri "lena.jpg"]];
  r:binding [ r:variable [ n3:uri "var#thumbnail"];
              r:boundTo  [ a r:Existential; n3:nodeId "_:sk3"]];
  r:binding [ r:variable [ n3:uri "var#x2"];
              r:boundTo  [ a r:Existential; n3:nodeId "_:sk4"]];
  r:binding [ r:variable [ n3:uri "var#x3"];
              r:boundTo  [ a r:Existential; n3:nodeId "_:sk5"]];
  r:rule <#lemma6>. # extracted by parsing description_smallThumbnail.n3

<#lemma3> a r:Inference;
  r:gives { _:sk0 http:methodName "POST".  _:sk0 http:requestURI "/images/".
            _:sk0 http:body <lena.jpg>.
            _:sk0 http:resp _:sk1.         _:sk1 http:body <lena.jpg>.
            <lena.jpg> ex:comments _:sk2.  <lena.jpg> ex:smallThumbnail _:sk3. };
  r:evidence (<#lemma4>); # extracted by parsing agent_background_knowledge.ttl
  r:binding [ r:variable [ n3:uri "var#image"];
              r:boundTo  [ n3:uri "lena.jpg"]];
  r:binding [ r:variable [ n3:uri "var#x1"];
              r:boundTo  [ a r:Existential; n3:nodeId "_:sk0"]];
  r:binding [ r:variable [ n3:uri "var#x2"];
              r:boundTo  [ a r:Existential; n3:nodeId "_:sk1"]];
  r:binding [ r:variable [ n3:uri "var#x3"];
              r:boundTo  [ a r:Existential; n3:nodeId "_:sk2"]];
  r:binding [ r:variable [ n3:uri "var#x4"];
              r:boundTo  [ a r:Existential; n3:nodeId "_:sk3"]];
  r:rule <#lemma7>. # extracted by parsing description_upload.n3

<#lemma4> a r:Extraction. <#lemma5> a r:Extraction. # Parsing details omitted for brevity
<#lemma6> a r:Extraction. <#lemma7> a r:Extraction. # (must be present in an actual proof).
Figure 4: This proof shows that a thumbnail of lena.jpg can be obtained by a composition of a POST and a GET request. The properties of these requests are detailed in the proof through instantiated descriptions.
Proofs provide lookahead functionality that serves as a machine substitute for people’s intuition on possible further steps.
We can make three core observations about a composition proof, assuming that all of the used descriptions accurately reflect reality. First, the existence of the proof indicates the desired goal is reachable given the current knowledge and Web APIs. Independent of whether we’ll execute the composition (and whether each of its steps will be successful), it is at least theoretically possible to reach the goal. This might not really seem a significant achievement, but remember that hypermedia-driven clients can only see the direct next steps; the steps thereafter are unclear for automated agents.
Second, one way of achieving the goal is the Web API composition suggested in the proof. Even though not all of the parameters are fully determined yet—
The trade-off between following hypermedia controls and executing HTTP requests directly is featured in the next chapter.
Third, each composition has at least one fully determined API call. This is indeed a logical consequence of the structure of proofs: one of the present RESTdesc descriptions must have been instantiated solely with data from extractions or regular inferences. This request is usually the first that is executed through hypermedia. Furthermore, in those cases where relevant hypermedia controls are unavailable, the agent can execute the HTTP request as described in the proof. This happens for instance when two resources from different applications are not connected. For example, the RESTdesc description of the image upload relies on a hard-coded URL instead of hypermedia. This means we could take an image from any application and upload it into the current one, even if there is no control that affords this.
Although the example proof presented here was rather simple, more complex proofs can be realized. In particular, this proof’s composition is a linear concatenation of Web APIs, whereas in the general case, complex interdependency patterns between API calls are possible. As proofs prohibit circular dependencies, an executable order of requests will always exist. Branches in the proof graph that are independent of others can be executed in parallel; the proof makes the dependencies visible through the various propagating placeholders represented by blank nodes.
Ontologies compensate for possible vocabulary mismatches between API descriptions from various providers or applications.
Just like in any other proof, regular N3 rules and RDF or OWL ontological constructs can also serve as inferences. Mixing them with RESTdesc rules can lead to the derivation of new facts even before API calls have been executed—
Pragmatic proofs for planning
Pre-proofs and post-proofs
Proofs are typically not regarded pragmatic, as they quite rigorously verify facts. Our pragmatic angle captures the usage of such a strict method to control a process that is inherently error-prone.
The method we’ve introduced for Web API composition should be considered a pragmatic proof [8]. We call it pragmatic
because it realizes composition generation, at the cost of accepting that things can (and will) go wrong every once in a while—
As a result, composition proofs rely on stronger assumptions than regular proofs. Whereas proofs are normally rooted in knowledge and rules that have to be trusted (or proven in turn), proofs with RESTdesc rules inherit the assumptions of these Web API descriptions. Concretely, any RESTdesc rule assumes a request exists that derives the postconditions from the preconditions. This allows the reasoner to propagate these postconditions throughout the proof. Should such request not exist (for instance, because the server has crashed), the proof is invalid because of unjustified premises. In order to make these assumptions explicit, we distinguish between two kinds of proof during the process of the execution:
- A pre-execution proof (pre-proof) assumes the execution of all described Web API calls will behave as expected.
- A post-execution proof (post-proof) contains static data as evidence, obtained through executing Web API calls.
Any client could prohibit RESTdesc descriptions as fact sources to guarantee that requests are already executed.
As each proof details the sources that were used to generate it, we can automatically verify what the assumptions were and hence the degree of trust we need. If the extractions contain RESTdesc rules, we need to be aware of the extra degree of trust needed. Therefore, a recommended practice is to indicate this explicitly in resources that contain RESTdesc descriptions.
The information gathered during proof creation can serve as provenance [9].
Note that the above distinction between a pre- and post-proof is relative rather than absolute. A complete pre-proof is generated before any execution has taken place, such as the proof in Figure 4. Analogously, the generation of a complete post-proof happens after all executions were performed. However, each execution can have its own pre- and post-proof. After one of the API calls from the complete pre-proof has been executed, a post-proof at this stage replaces that single API call by its results, which were determined by the execution.
In the previous chapter, the first step did involve hypermedia controls; it depends on the use case.
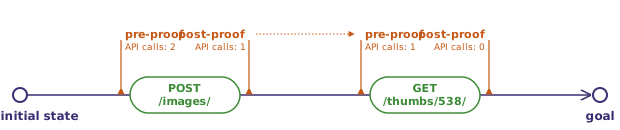
As an example, we will apply the concept of pre- and post-proofs on the image upload scenario, as part of the execution process detailed in the previous chapter. The proof in Figure 4 is a pre-proof and forms the agent’s initial plan. It contains two API calls, a GET and POST request, and only the latter has all necessary parameters in place for execution. The agent therefore starts with the POST request. As there are no hypermedia controls in this particular case, the request is executed as listed in the proof.
Reasoners will strive to obtain the shortest proof, so we’re sure the number of APIs doesn’t increase.
In response, the server returns a representation that, as expected from the API description, contains a smallThumbnail link. For instance, assume the link points to /thumbs/538/. The classical planning strategy would be to continue from the initial proof, as we now know that the existential _:sk3 is bound to /thumbs/538/. In contrast, the agent first verifies the success of the request by generating a post-proof from the initial state, the response, and the API descriptions. If successful, this post-proof should contain one less API call, as the needed smallThumbnail triple is now present as a fact and needs not be derived. In case of failure, the post-proof will again suggest the same POST request or result in a contradiction. In that case, the corresponding description may not be used again, and a new pre-proof should be generated.
In the final post-proof, the goal follows directly from the combination of background knowledge and obtained API results.
A successful post-proof generated after this first request can directly serve as a pre-proof to continue with the next request. Indeed, it will contain all remaining API requests. However, to make the request, the agent can simply follow the smallThumbnail link in the representation, as the necessary hypermedia control is present. The interaction thus continues in a hypermedia-driven way, with pre-proofs as a guideline toward the next step, and post-proofs to verify the correctness of the previous step. After following the link, the agent receives a thumbnail. The reasoner can generate another post-proof from this, but it will be rather short: the goal of having a thumbnail is now directly implied by the facts.
The diagram below summarizes the role of pre- and post-proofs in this example execution. Note in particular how the decreasing number of API calls in the proof indicates the goal is approaching. Also, the correspondence of a successful post-proof to the subsequent pre-proof is highlighted. This illustrates the pragmatic role of proofs in hypermedia-driven execution.
Performance of composition and selection
As of mid-2013, the widely known Web API directory ProgrammableWeb listed more than 10,000 APIs [10].
We still need to tackle the most pragmatic of all questions on the Web: does it scale? Is proof-based composition generation a feasible strategy given an ever increasing number of Web APIs? The success of our approach depends on whether state-of-the art N3 reasoners are able to generate proofs within a reasonable amount of time. In practice, the composition time should be negligible compared to the execution time of the API calls.
To verify this, we have created a benchmark suite [11] that generates test descriptions in such a way they can be composed into graphs of a chosen length. Web API calls can depend on any number of others. By varying the length and the number of dependencies between calls, we can investigate the influence on performance. Below are results obtained by the EYE reasoner on a 2.66 GHz quad-core CPU (times in milliseconds).
| number of APIs | 4 | 8 | 16 | 32 | 64 | 128 | 256 | 512 | 1,024 |
|---|---|---|---|---|---|---|---|---|---|
| 1 dependency | |||||||||
| parsing | 53 | 54 | 55 | 58 | 64 | 78 | 104 | 161 | 266 |
| reasoning | 4 | 5 | 7 | 11 | 20 | 43 | 77 | 157 | 391 |
| total | 57 | 58 | 62 | 70 | 84 | 121 | 181 | 318 | 657 |
| 2 dependencies | |||||||||
| parsing | 53 | 59 | 56 | 60 | 67 | 85 | 117 | 184 | 331 |
| reasoning | 6 | 69 | 41 | 45 | 56 | 84 | 174 | 461 | 1,466 |
| total | 59 | 128 | 97 | 104 | 123 | 169 | 292 | 645 | 1,797 |
| 3 dependencies | |||||||||
| parsing | 53 | 68 | 56 | 61 | 70 | 90 | 129 | 208 | 371 |
| reasoning | 12 | 45 | 49 | 61 | 99 | 200 | 544 | 1,639 | 6,493 |
| total | 66 | 114 | 105 | 122 | 169 | 290 | 673 | 1,847 | 6,864 |
Parsing time can virtually be eliminated by preloading Web API descriptions.
The total time has been split into the time used for the actual reasoning and proof generation on the one hand, and the startup and parsing time on the other hand, since parsing results can be cached. Note how a chain of 1,024 API calls with a single dependency takes less than a second to compose; the execution time of each of those calls could typically take up to a few hundred milliseconds already. More dependencies take longer, but are still manageable. Furthermore, the number of dependencies will be small in practice.
The other important aspect is selection time: how fast can a reasoner find relevant descriptions? Therefore, we tested compositions of length 32 with a variable number of dummy descriptions that looked similar to others, but were not relevant to the composition. Note how the reasoning time remains low, even with a high number of dummies (times in milliseconds).
| dummies | 1,024 | 2,048 | 4,096 | 8,192 | 16,384 | 32,768 | 65,536 | 131,072 |
|---|---|---|---|---|---|---|---|---|
| 32 APIs, 1 dep. | ||||||||
| parsing | 276 | 528 | 1,001 | 1,949 | 3,916 | 7,827 | 17,127 | 34,526 |
| reasoning | 12 | 20 | 18 | 68 | 107 | 113 | 122 | 228 |
| total | 289 | 548 | 1,019 | 2,018 | 4,023 | 7,940 | 17,249 | 34,754 |
Other composition approaches
The bulk of the work on composition on the Web has been performed in the context of classical Web services [12, 13]. The relatively recent interest in REST APIs, especially in industrial contexts, makes composition of REST APIs a yet underexplored topic—
In the decade following the year 2000, Web applications started evolving rapidly, and so did Web services and later Web APIs. Soon, the idea came to combine those different services in small applications called mashups, giving rise to a new generation of demand-driven applications [14]. A key question in this area is how to integrate different services with a minimum of case-specific programming.
Some approaches focus on the integration of REST APIs in existing tools and workflows. Pautasso extends the BPEL, normally targeted at traditional Web services, to REST APIs [15]. He explains how the composition for REST APIs is different because of the late binding to URI addresses and the use of a uniform rather than a specific interface. The extensions proposed in the paper enable manual BPEL composition methods to work in resource-oriented environments. In other work, he demonstrates the integration with the visual composition language JOpera, and outlines the important features a REST composition language should support [16]: dynamic late binding, the uniform interface, dynamic typing, content-type negotiation, and state inspection. An alternative model is provided by Bite [17]. Bear in mind that the composition creation still happens manually with these approaches; their contribution resides on the interface and data flow level.
Alarcón, Wilde, and Bellido acknowledge the significant mismatch between action-centric composition methods and REST, and propose a novel method based on Petri nets [18] with APIs described in the Resource Linking Language [19]. The hypermedia constraint forms a fundamental part of the method, as it focuses on hypermedia controls and their semantics. The downside of the approach is that the composition is static.
The difference with our method is that we strongly lean toward the agent vision of the Semantic Web, combined with the hypermedia-driven viewpoint of REST. Our aim is to have an autonomous agent that consumes Web APIs to satisfy a given goal. Pre- and post-proofs enable a flexible way to adaptively respond in an interaction.
When trying to reach a complex goal, agents need to plan beyond the initial next steps offered in hypermedia-driven interactions. Proofs can combine RESTdesc descriptions into a composition, designed to meet the demands of a predefined goal. By distinguishing between pre- and post-proofs, the assumption of successful execution can be made explicit, while still obtaining a correct proof in the classical sense. In contrast to most composition approaches, the composition plan serves only as a guidance—
References
- [1]
- Berners-Lee, T., Hendler, J. and Lassila, O. (2001), “The Semantic Web”, Scientific American, Vol. 284 No. 5, pp. 34–43, available at: http://www.scientificamerican.com/
article.cfm?id=the-semantic-web . - [2]
- Hendler, J. (2001), “Agents and the Semantic Web”, Intelligent Systems, IEEE, Vol. 16 No. 2, pp. 30–37, available at: https://doi.org/
10.1109/ .5254.920597 - [3]
- Berners-Lee, T. (1998), “What the Semantic Web can represent”, December, available at: http://www.w3.org/
DesignIssues/ .RDFnot.html - [4]
- Berners-Lee, T., Connolly, D., Kagal, L., Scharf, Y. and Hendler, J. (2008), “N3Logic: A logical framework for the World Wide Web”, Theory and Practice of Logic Programming, Cambridge University Press, Vol. 8 No. 3, pp. 249–269, available at: https://doi.org/
10.1017/ .S1471068407003213 - [5]
- Berners-Lee, T. (2005), “Semantic Web Application Platform”, available at: http://www.w3.org/
2000/ .10/ swap/ - [6]
- Berners-Lee, T. (2000–2009), “cwm”, available at: http://www.w3.org/
2000/ .10/ swap/ doc/ cwm.html - [7]
- De Roo, J. (1999–2013), “Euler Yet another proof Engine”, available at: http://eulersharp.sourceforge.net/.
- [8]
- Verborgh, R., Arndt, D., Van Hoecke, S., Coppens, S., De Roo, J., Steiner, T., Mannens, E., et al. (2014), “The Pragmatic Proof: Hypermedia-driven Web API Composition and Execution”.
- [9]
- Groth, P. and Moreau, L. (2013), PROV-Overview, Working Group Note, World Wide Web Consortium, available at: http://www.w3.org/
TR/ .prov-overview/ - [10]
- Berlind, D. (2013), “ProgrammableWeb’s Directory Hits 10,000 APIs. And Counting.”, ProgrammableWeb blog, 23 September, available at: http://blog.programmableweb.com/
2013/ .09/ 23/ programmablewebs-directory-hits-10000-apis-and-counting/ - [11]
- Verborgh, R. (2012), “RESTdesc composition benchmark”, available at: https://github.com/
RubenVerborgh/ .RESTdesc-Composition-Benchmark - [12]
- Milanovic, N. and Malek, M. (2004), “Current solutions for Web service composition”, Internet Computing, IEEE, Vol. 8 No. 6, pp. 51–59, available at: https://doi.org/
10.1109/ .MIC.2004.58 - [13]
- Rao, J. and Su, X. (2005), “A Survey of Automated Web Service Composition Methods”, in Cardoso, J. and Sheth, A. (Eds.), Semantic Web Services and Web Process Composition, Vol. 3387, Lecture Notes in Computer Science, Springer, pp. 43–54, available at: https://doi.org/
10.1007/ .978-3-540-30581-1_5 - [14]
- Benslimane, D., Dustdar, S. and Sheth, A. (2008), “Services Mashups: The New Generation of Web Applications”, Internet Computing, IEEE, Vol. 12 No. 5, pp. 13–15, available at: https://doi.org/
10.1109/ .MIC.2008.110 - [15]
- Pautasso, C. (2009), “RESTful Web service composition with BPEL for REST”, Data & Knowledge Engineering, Vol. 68 No. 9, pp. 851–866, available at: https://doi.org/
10.1016/ .j.datak.2009.02.016 - [16]
- Pautasso, C. (2009), “Composing RESTful Services with JOpera”, in Bergel, A. and Fabry, J. (Eds.), Software Composition, Vol. 5634, Lecture Notes in Computer Science, Springer, pp. 142–159, available at: https://doi.org/
10.1007/ .978-3-642-02655-3_11 - [17]
- Rosenberg, F., Curbera, F., Duftler, M.J. and Khalaf, R. (2008), “Composing RESTful Services and Collaborative Workflows: A lightweight Approach”, Internet Computing, Vol. 12 No. 5, pp. 24–31, available at: https://doi.org/
10.1109/ .MIC.2008.98 - [18]
- Alarcón, R., Wilde, E. and Bellido, J. (2011), “Hypermedia-Driven RESTful Service Composition”, in Service-Oriented Computing, Vol. 6568, Lecture Notes in Computer Science, Springer, pp. 111–120, available at: https://doi.org/
10.1007/ .978-3-642-19394-1_12 - [19]
- Alarcón, R. and Wilde, E. (2010), “Linking Data from RESTful Services”, in Proceedings of the 4th Workshop on Linked Data on the Web, available at: http://events.linkeddata.org/
ldow2010/ .papers/ ldow2010_paper10.pdf