Chapter 4: Functionality
How do you do the things that you do?
No one I know could ever keep up with you
How do you do?
Did it ever make sense to you? Roxette, How Do You Do! (1992)
For people, navigating hypermedia feels entirely natural. We read texts, view images and video, and through them, we can not only reach the next piece of information we need; we can also perform actions that modify things in a predictable way. Machines face far greater difficulties. Even if they can interpret the information on a page, it’s currently difficult for them to understand the impact of change. Therefore, we’ve developed RESTdesc, a method to describe the functionality of hypermedia controls in applications. Unlike other approaches, it focuses on enabling autonomous agents to use Web applications in a hypermedia-driven way.
Unfortunately, on today’s Web, many APIs circumvent the uniform interface by adding methods to the URL or the message body. These APIs then lose desirable properties of REST, moving the interpretation from the message to out-of-band documentation.
The uniform interface constraints of the REST architectural style mandate that messages be self-descriptive [1]. This is why HTTP adopts standard methods that act on resources, as opposed to many other remote protocols that allow the definition of any method. The uniform interface brings simplicity through universal understanding: a software agent knows that GET retrieves a document and that DELETE removes it. However, there is only so much that can be expressed in a uniform interface. Every application offers specific functionality that cannot be accounted for unambiguously in a specification that applies to any Web application.
Sometimes, POST is even used in those cases where another standard HTTP method is perfectly applicable, stretching its semantics beyond what was accounted for. Part of the explanation for this non-standard usage is that HTML only supports GET and POST on forms, even though it offers the other methods through JavaScript.
The POST method essentially encompasses everything no other standard method provides. In the HTTP specification, it is defined to cover annotation of resources, message posting, data processing, and database appending, but the actual function performed by the POST method is determined by the server and is usually dependent on the request URI
[2]. This means that, for any POST request, the message is self-descriptive in the sense that it asks for an action that follows the definition, but that definition is so uniform that we don’t know what exactly is going on. On the protocol level, we understand the message. On the application level, we don’t—
Describing functionality
Design goals
RDF could capture functionality indirectly, but this would necessitate an interpretation that is not native to RDF processors.
RDF, as its expansion to Resource Description Framework
indicates, has been created for the description of resources, the unit of information in the REST architectural style. RDF captures the state of a resource at a given moment in time, but it cannot directly capture state changes. We need a method for dynamic information that conforms to the following characteristics.
The last four goals refer to REST’s uniform interface constraints [1]: resource-orientation, manipulation through representations, self-describing messages, and hypermedia as the engine of application state.
- The goal of descriptions is to capture functionality: expressing the relation between preconditions and postconditions.
- Consumers should require no additional interpretation beyond knowledge of HTTP.
-
Descriptions should be resource-oriented: they should describe on the level of application-specific resources, not in terms of generic concepts such as
services
orparameters
. -
Resources should be described in a representation-independent way—
the media type is determined at runtime. - Each description can be interpreted independently of others.
- The runtime interaction should remain driven by hypermedia: descriptions support the interaction but do not determine it.
With these goals in mind, we can derive the foundations of a method to describe the functionality of those Web APIs that conform to all REST constraints, indicated by the term hypermedia APIs [3].
Description anatomy
In essence, there are three things we need to capture: preconditions, postconditions, and the HTTP request that allows the state transition from the former to the latter. The other properties depend on the design choices we make. Those three components are related to each other as follows. Given a set of preconditions on a resource , a description of an action should express what request is necessary to obtain a set of postconditions . We could represent this relationship schematically as follows:
The preconditions only imply the postconditions through the execution of the request.
The fact that the implication is fulfilled by executing the request is symbolized by indicating it on top of the implication arrow, but we still need to formalize this meaning. A naive conversion to first-order logic treats the request as a part of the precondition:
Having preconditions in the antecedent does not account for errors that are likely to happen in distributed systems and is thus insufficient.
The above equation expresses that, if the preconditions are fulfilled, an execution of the request will always lead to the postconditions. However, this cannot be guaranteed in practice. On large distributed systems such as the Web, requests can fail for a variety of reasons. Therefore, we can only state that a hypothetical request exists that makes the postconditions true:
Preconditions in the consequent align best with reality: some successful request exists, but that doesn’t guarantee success for each similar request.
So given preconditions , there always exists a request for the action on the resource for which postconditions hold. We cannot be sure whether all requests that look like will succeed, since several components can fail, but we can attempt to construct . Consequently, this is the model we will use for descriptions.
While monotonicity is not strictly required, it makes reasoning simpler and is a prerequisite to generate proofs, wherein the use of retractable facts would be problematic.
This design choice is also necessary to avoid introducing a logical contradiction in the process. Indeed, if we had modeled the request in the antecedent of the rule, and its execution would fail for any reason, then we couldn’t combine the prior knowledge about the action (the preconditions and request always lead to the postconditions
) and the posterior knowledge (the request has been executed but the postconditions do not hold
) in a monotonic logic environment. Additionally, the existential formulation allows triggering
the rule before the request has been issued—
Expressing descriptions
The presence of variables and quantification suggest that regular RDF won’t possess the expressivity needed to convey these descriptions. As indicated in the previous chapter, Notation3, an RDF superset, does provide this support. Additionally, we need a vocabulary to detail HTTP requests: the existing HTTP vocabulary in RDF
[4] provides all necessary constructs. The combination of N3 and this vocabulary form the functional Web API description method I named RESTdesc [5, 6]. The skeleton of a RESTdesc description looks like this:
The specified preconditions on a resource imply the existence of a certain request that effectuates postconditions on this resource. Variables like ?resource are universally quantified; blank nodes such as _:request are existentially quantified [7].
{
  ?resource  …  … .
}
=>
{
  _:request http:methodName […];
            http:requestURI […];
            http:resp […].
  ?resource  …  … .
}.
For instance, the following description explains that you can receive an 80px-high thumbnail of an image by performing a GET request on the link labeled ex:smallThumbnail:
Actually, this RESTdesc description explains what the ex:smallThumbnail relation means in terms of non-local predicates, for instance those from DBpedia. In contrast to traditional
ontologies, the meaning expressed here is operational: it details what happens when a certain request is executed upon the object.
The ex: prefix is local to the application; agents aren’t assumed to already understand it.
@prefix ex: <http://example.org/image#>.
@prefix http: <http://www.w3.org/2011/http#>.
@prefix dbpedia: <http://dbpedia.org/resource/>.
@prefix dbpedia-owl: <http://dbpedia.org/ontology/>.

{
  ?image ex:smallThumbnail ?thumbnail.
}
=>
{
  _:request http:methodName "GET";
            http:requestURI ?thumbnail;
            http:resp [ http:body ?thumbnail ].

  ?image dbpedia-owl:thumbnail ?thumbnail.
  ?thumbnail a dbpedia:Image;
             dbpedia-owl:height 80.0.
}.
Let’s examine this example description, considering the design goals.
Basic knowledge of HTTP is the only constraint we put on agents, and this is reasonable since they need HTTP in any case. All other knowledge is domain-specific; we should strive to use Linked Data so the agent can look up any unknown terms autonomously. RESTdesc is not limited to APIs that communicate in RDF, but those APIs that do have several benefits, as we’ll see in Chapter 7.
-
The description captures functionality, in the sense that it expresses the
ex:smallThumbnailrelation not in a static, ontological way, but from the viewpoint of an HTTP request it affords, and the properties a result of this request will have. This allows an agent to decide whether to issue the request, based on the desirability of its effects. -
To generate the request, agents only need to understand the
httpontology, which is universal to all RESTdesc descriptions. This particular description also uses an application-specificexontology and DBpedia resources. An agent doesn’t need knowledge about theexontology, as the description explains the used predicate. The usage of DBpedia concepts seems to cause more difficulties for agents, however, any agent consuming this API will have to deal with images in some way, even if only implicitly through goals set by the user. Since DBpedia is published as Linked Data, we assume the agent is able to mapdbpedia:Imageto its own understanding ofimage
if required. - The description is resource-oriented: it focuses on the actual application domain (images and thumbnails) instead of a meta-level (such as services or parameters).
- The representation is not fixed and can be determined at runtime: the description only explains that the image will be a thumbnail of the original image and that it will have a height of 80 pixels.
- No other descriptions are needed for interpretation. For instance, it does not matter how the original image is created.
-
The description supports hypermedia-driven interactions, as it doesn’t contain fixed URLs or templates. Rather, it expresses the fact that if we follow an image’s
smallThumbnaillink through hypermedia, then we can perform aGETrequest on this link’s target, which will result in a resource with these properties.
GET requests are safe and idempotent, so they may not change resource state. In contrast to the unsafe POST requests, they are defined strictly and narrowly. That doesn’t mean there’s no use for descriptions—
One can question the utility of describing a GET request, since the HTTP specification specifies this method already in detail [2]. The answer is twofold. On the one hand, dereferencing is assumed within Linked Data, so we can indeed omit the implied GET request in descriptions. On the other hand, the description above conveys an expectation: it tells that the representation will be a thumbnail of the original image. This can save us the GET operation if we don’t need that. More importantly, it can guide an agent when planning a sequence of steps: even if an image has not been created yet, the agent knows it will be able to get its thumbnail.
Functional descriptions are certainly necessary for methods that are intentionally underspecified, such as HTTP POST. Depending on the resource URI, a wide variety of actions might happen. RESTdesc narrows this down to what is described. For instance, the following N3 rule states that an image posted to an album receives comments and thumbnail links.
No restrictions are placed on ?image; it can be an image on the local file system, or any image on the Web. These details are agreed on at runtime. During planning, it suffices to know that POSTing the image will lead to the described effects.
{
  ?profile ex:hasAlbum ?album.
  ?image a dbpedia:Image.
}
=>
{
  _:request http:methodName "POST";
            http:requestURI ?album;
            http:body ?image;
            http:resp [ http:body ?image ].
  ?image ex:comments _:comments;
         ex:smallThumbnail _:thumb;
         ex:mediumThumbnail _:mediumThumb;
         ex:belongsTo ?album.
}.
It seems as if the response (in http:resp) to POSTing the image is the image itself. However, REST accesses resources through representations: we send a representation of the image and receive another, augmented with links.
This description captures an action that requires a link to an album and, independently thereof, an image. The image can then be used in the body of a POST request on the album, and this will establish a belongsTo relation between the image and the book. Furthermore, the image will provide access to links for comments and thumbnails. Note that the previous description explained the smallThumbnail relation, so the two descriptions together inform an agent that, after uploading an image, it can retrieve the corresponding 80px-high thumbnail.
The fact that the consequent of every POST rule can be deduced if its preconditions are satisfied follows from our design choices, since the rules were created to contain the hypothetical request
that makes the postconditions become true.
Upon critical inspection of the rule, an apparent contradiction should be clarified. The consequent of an N3 rule is a conjunction of triples, but implies . Thus, omitting the HTTP request from the rule is a semantically valid operation. Unfortunately, this doesn’t correspond to reality: the mere existence of an album and an image does not necessarily mean they are connected in any way. Yet, we must accept the limitations of first-order logic: it doesn’t have a time aspect; everything that can be true is instantaneously true. Therefore, any POST request that can be executed is assumed to be executed
, or at least, its effects can serve as input for other rules. When used to our advantage, this is a useful property for planning.
Hypermedia-driven execution
The role of descriptions
Describing Web APIs is only one part of the solution. Software agents have to consume these descriptions as part of their process to meet a certain goal set out by the user. This might seem contradictory, since the hypermedia constraint demands that the interaction be driven by hypermedia controls in order to guarantee the independent evolution of client and server; out-of-band information should not be necessary to engage in the interaction. However, there are two remarks on this.
The act of navigating in a hypermedia-driven way is sometimes expressed colloquially as following your nose
. Indeed, at each step, you can look around and choose where to go next, as if by chance. However, following one’s nose is easy for people, as we ultimately know the overall direction in which we’re heading. In fact, this is a form of out-of-band information—
First, for humans, it is straightforward to use hypermedia, as we often have implicit out-of-band knowledge of what we want to achieve. For instance, suppose we want to buy a certain book online. Before we even start, we know we will end up on a site that offers several books for sale. One way to start would be to type the book’s title into a search engine, which (as we expected) will give us links to book sites. We can click one of them, and we assume there will be a link add to shopping basket
or similar. Before we click that link, we know this will eventually let us pay for the items in the basket and choose a delivery method. So while the actual interaction is driven by hypermedia, the driver behind the process is planning, which is based on expectation and intuition, implicit forms of out-of-band information. Machines don’t have this kind of intuition, and the descriptions provide the expectations they need for planning the interaction—
Most descriptions have traditionally been used at design time, where they indeed served an out-of-band role. The application was compiled against a certain description, and then unable to work with other APIs or versions. RESTdesc descriptions are designed for runtime use.
Second, the problem with out-of-band knowledge in REST architectures is that this information is in practice interpreted by a human and then hard-coded into the system. For instance, in an RPC API, where the interaction is not driven by hypermedia, the steps have to be preprogrammed in the client software. This limits the client’s capabilities to a certain API—
In conclusion, runtime descriptions are no more out-of-band than intuition and expectation, which makes them harmless.
The interaction from begin to end
The agent should be as generic as possible, so it doesn’t need any domain-specific knowledge; only an understanding of HTTP.
Having discussed the role of descriptions for autonomous agents, we now investigate how the actual hypermedia interaction will happen. As summarized in the schema below, the agent starts from a set of instructions and discovers descriptions that it uses to create a plan, based on the currently available knowledge. The first step of the plan is executed, and its results are evaluated and added to the knowledge base. If the goal is not reached yet, a new plan is created from the current starting point and the loop continues. Otherwise, the agent reports an answer (or error) back to the user.
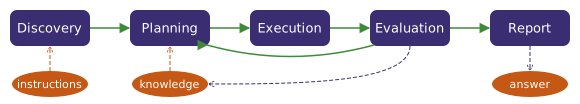
Receiving instructions
First, the user sends instructions to the agent. One way is to set a certain goal that must be met, given some background knowledge. For instance, the background knowledge here includes the fact that the user has an online photo album:
<http://example.org/profiles/lisa>
  ex:hasAlbum <http://example.org/albums/453>.
The user’s goal is to obtain a thumbnail of a chosen image:
<http://www.w3.org/images/logo>
  dbpedia-owl:thumbnail ?logoThumbnail.
Discovering descriptions
Humans can deal with incompleteness: we often have an idea of the initial and last steps, and assure ourselves we’ll find a way to get through the middle. Machines need concrete plans: only if all steps are there, they can determine if the goal can be reached. Therefore, they absolutely require a description for each step.
Next, the agent needs to find descriptions to understand the possible actions. Broadly speaking, there are three ways to make this happen. First, the hypermedia-driven way would be to start from the background knowledge. For instance, starting from the photo album, the agent looks for links toward descriptions. These might be organized similarly to current human-readable API documentation pages, with a homepage leading to deeper topics. However, it might be difficult to find the right starting point in a large knowledge base. Therefore, a second approach is to consult an index or repository of descriptions (similar to search engines). In this case, the query would consist of the dbpedia-owl:thumbnail predicate. The third option is to dereference this predicate, since it might link to relevant descriptions.
Planning
The technique to generate a plan from RESTdesc descriptions is explained in detail in the next chapter. A plan’s core consists of instantiated descriptions.
Once the descriptions have been retrieved, the agent creates a plan that, given the background knowledge, finds steps that lead toward the goal. These steps use resources and their links as high-level concepts. For instance, the plan in our example will instruct to post the image to an album, and then to follow the smallThumbnail link—
Executing
Execution is similar to how we browse webpages: guided by some plan, but driven by hypermedia.
The first step of the plan is read and executed through hypermedia. Even though simply phrased, this is the crucial step that makes this method different from others. Through hypermedia
means that the step, an instantiated description, will guide the action, although hypermedia is used to execute it. Concretely, in our example, the description’s antecedent
?profile ex:hasAlbum ?album.
?image a dbpedia:Image.
will have been instantiated in the plan with background knowledge as
The instantiation can be performed by a regular N3 reasoner, as will be detailed in the next chapter. The agent does thus not need N3 parsing or manipulation; regular RDF knowledge is sufficient.
<http://example.org/profiles/lisa>
  ex:hasAlbum <http://example.org/albums/453>.
<http://www.w3.org/images/logo> a dbpedia:Image.
and, as a result of this binding, the request in the consequent will be
_:request http:methodName "POST";
  http:requestURI <http://example.org/albums/453>;
  http:body <http://www.w3.org/images/logo>;
Executing this request directly is difficult, because we don’t know in what format we should send the image. Instead, we consult the original resource /albums/453, asking for a machine-readable representation, and look for the form that allows uploading an image. This will tell us whether we have to send the URL directly or, for instance, a JPEG representation. Therefore, through the hypermedia controls inside the representation of /albums/453, the agent uploads the image. Even before it performs the upload, the rest of the instantiated description conveys expectations of what will happen:
Only image and album have been instantiated, because they were bound variables in the description; the others were not.
<http://www.w3.org/images/logo>
   ex:comments _:comments;
   ex:smallThumbnail _:thumb;
   ex:mediumThumbnail _:mediumThumb;
   ex:belongsTo <http://example.org/albums/453>.
In other words, the uploaded image will have comments, thumbnails, and will belong to the album. Note how the actual URLs of the comments and thumbnails are still unknown; they will only be filled out once the request has been executed. Nonetheless, the fact that there will be some thumbnail link has been sufficient for the planner to schedule the next step, which is to follow the concrete smallThumbnail link once the server sends it.
Evaluating and replanning
Replanning is important. In the simplest case, if everything went as expected, then the new plan is simply the current plan without its already completed first step. This stage is where the expectation will be checked against reality (in contrast to RPC-style interactions, where the entire control flow is fixed). It enables the agent to accurately respond to any situation at hand.
The challenge of interacting with distributed systems is that things don’t always go according to plan. Even though the agent has several assumptions about what the response will look like, there can never be a guarantee. Instead of steadily continuing with the plan, the agent inspects the hypermedia response and extracts all machine-interpretable knowledge. In the worst case, the response crucially differs from the expectation, and the goal will have to be reached in another way. But in the best case, the response brings us actually closer to the goal, maybe even more than anticipated. We’re all familiar with this aspect on the Web: navigation happens serendipitously. The agent then verifies whether the goal state has been reached. If not, the background knowledge is augmented with the extracted knowledge, and the agent goes back to the planning step. The same goal still has to be reached, but it should now be closer than before (even if this means we’ll have to find a different way).
Here, the new plan will contain the concrete link to the thumbnail, which was found inside the image representation returned by the server after the upload. In the subsequent execution step, the agent will simply have to GET the link’s target to obtain the thumbnail.
Reporting
In addition, real-world effects of the action might also have occurred, if they were part of the goal.
If the evaluation phase reveals the goal has been reached, then the answer is reported back to the user. Should, for any reason, the goal turn out to be unreachable, then the current status and the reason for failure are displayed. The same happens with any irrecoverable errors that cannot be solved by replanning.
This process indicates how descriptions and hypermedia can work together to support dynamic complex interactions between a client and a server in an evolvable way. Even though the descriptions and the corresponding HTTP request have been instantiated in the initial plan, the hypermedia response is inspected at every step and the current plan is adjusted according to the obtained result. Furthermore, the application state will only be advanced through the hypermedia controls supplied by each representation.
Limitations
RESTdesc does not strive to be a solution for all semantic agent requirements. Rather, it focuses on performing well in a broad range of cases. Below, we discuss limitations and possible coping strategies.
DELETE is an especially tricky method: in monotonic logic, a given thing that exists cannot unexist. However, we could mark it as deleted
with a flag.
RESTdesc is expressed in N3 rules, which are implications in a monotonic first-order logic system. This limits what we can express. In particular, monotonicity means that we cannot retract statements after they have been asserted, which can give rise to inconsistencies. For instance, suppose a photograph is either private or public, and that this can be changed through a PUT request. Then we have a description that expresses if the visibility is
. However, since a first-order world has no notion of time (everything that can be true is true), this implies that the photograph is private, contradicting the fact that it was public. However, this is seldom a problem in practice. First, reasoning under constraints is always difficult; therefore, over-restrictive knowledge should be avoided (as is common with ontologies as well). Second, methods such as public
, then it can become private
PUT and DELETE are already precisely specified by HTTP and do not need application-specific clarification, unlike POST. Third, the interaction process demands replanning in every step. Therefore, facts that conflict with acquired knowledge can be omitted from later stages, as they are no longer relevant.
Without hypermedia, the glue between two related resources isn’t a control, but rather some common piece of information.
Next, RESTdesc descriptions rely on the hypermedia constraint, as they assume a link in the precondition. However, such a link is not always present: what if we want to reuse a resource from one Web API in another, but the APIs do not link to each other? The answer is to use descriptions that make the link on the semantic level instead:
For brevity, we use a list to express URI construction, but more sophisticated mechanisms such as URI templates offer a flexible alternative.
{ ?book dbpedia-owl:isbn ?isbn. }
=>
{
  _:request http:methodName "GET";
            http:requestURI
              ("http://books.org/" ?isbn "/cover");
            http:resp [ http:body _:cover ].
  ?book dbpedia-owl:thumbnail _:cover.
}.
Cases of missing links will be discussed in detail in Chapter 6, where descriptions without a link in the antecedent are crucial.
The above description expresses that if you have the ISBN number of a book, you can construct a URL that will lead to an image of its cover. This allows an agent to go from any page to the book API, even if that page doesn’t provide the link. While this is hardly hypermedia-driven, when the page doesn’t afford the action we need, it’s our only option.
Alternative description methods
Web service descriptions
We haven’t discussed Web services so far, because I don’t consider them first-class Web citizens. They exist and have a use, but they operate by a separate protocol on top of HTTP (or even something else) and thus don’t integrate with hypermedia at all. REST APIs instead function on the level of the Web.
The idea of describing dynamic interactions on the Web has been around for a long time, with substantially varying approaches depending on the underlying technology. The first generation of dynamic content was brought by Web services, the idea of which is to exchange messages (mostly in XML) over HTTP in a way that enables remote procedure calling. The most widely-known Web service protocol is the SOAP [8]. A client sends a SOAP XML message to a server, typically containing a specific action name and its parameters, to which the server replies with another SOAP XML message. Note that SOAP neither uses hypermedia nor conforms to other REST uniform interface principles, as it works with an action/
A WSDL document can be compared to a header file of a shared library on a local system. Such a file details in a machine-processable way how to interact with the library, but does not explain its provided actions.
Interacting with SOAP services requires out-of-band knowledge. The WSDL [9] describes the interactions that are possible and what each message should look like. According to its specification, WSDL also allows to describe the abstract functionality provided by Web services. However, the definition of functionality
is different from what we’ve assumed in this chapter. In a WSDL description, the interface element explains the supported operations of the service and the input and output parameters each operation requires. The notion of functionality is thus limited to the knowledge of a set of supported method names and their parameters, similar to a method signature in statically typed programming languages, albeit in a generic and platform-independent way. As a result, WSDL descriptions do not provide sufficient information for machines to decide whether the functionality offered by the service matches their current goals.
In contrast, functionality
in the context of RESTdesc means that machines are able to match the description of a Web API to their own knowledge base and/understanding
in the Semantic Web sense of the word—
SOAP tries to fit the Web into the classical programming paradigm, which is not built to withstand constant evolution.
WSDL descriptions can serve as a contract during development. Tools can automatically generate code for the communication with WSDL-described services, expressing them in a programming language’s usual abstractions. Unfortunately, this closely ties applications to the services offered by one server at a specific moment in time.
The WSMO is the other well-known semantic Web service description method [10].
Web services played an important part in the initial Semantic Web vision [11]. Therefore, much of the early work focused on making services accessible for machines through semantic service descriptions. One of the results of those efforts is OWL-S [12]. OWL-S descriptions are expressed in RDF and consist of three parts: a profile, a process model, and a service grounding. The profile advertises what the service offers, using input and output parameters, preconditions and results. These last two are expressed as literals in specialized languages, embedded in the main RDF document. They capture functionality in the Semantic Web sense, explaining the result of a service invocation in terms of parameter relations. The process model is meant to detail the interaction more precisely and comes into play when the client actually wants to use the service. Finally, the grounding explains how the parameters are captured in an actual exchange between a client and a server.
OWL-S comes with WSDL support built in. However, it allows for extension with other groundings, for instance, SPARQL [13].
Besides the focus on Web services instead of REST Web APIs, the difference between OWL-S and RESTdesc lies in the way they express functionality. First of all, OWL-S describes services on the meta-level, whereas RESTdesc conveys functionality on an API’s application domain level. Thus, in an OWL-S document, the interaction is described in terms of parameters, whereas RESTdesc uses the application’s concepts directly, thereby not enforcing a particular vocabulary or terminology. This is possible because RESTdesc assumes the underlying API conforms to the REST constraints, which demand resource-orientation.
OWL-S supports three expression languages by default, while enabling the addition of others such as N3 [14].
Second, the interpretation of conditions and results in OWL-S is not integrated, as these are expressed in external languages. Therefore, the interpretation of the RDF semantics of an OWL-S document does not imply an understanding of its functionality. With RESTdesc, the interpretation of the description and its functionality are integrated: the ability to parse N3 implies a correct interpretation of RESTdesc.
RESTdesc’s integration of a function and the HTTP request that affords it helps composition, as the next chapter will explain.
Third, RESTdesc describes the request together with the functionality, while OWL-S separates the description of what the service does from how this is achieved (although it only supports SOAP natively). While this gives WSDL more flexibility, it comes with a considerable overhead. Support for other groundings in RESTdesc was not considered, as we especially target hypermedia APIs.
The information density of RESTdesc is rather high, allowing to understand descriptions at a glance.
Finally, RESTdesc descriptions are substantially shorter than their OWL-S counterparts. A RESTdesc description contains typically between 10 and 20 lines of RDF, while OWL-S usually takes a hundred lines or a multiple thereof. Brevity was an important RESTdesc design consideration, which is partly enabled by the assumption of the REST constraints.
Web API descriptions
Together with several fellow API researchers, I’ve written a more comprehensive survey on Web API description [15]. This section provides a brief overview of our findings.
As Web APIs surpassed the popularity of Web services, methods for describing Web APIs emerged. This is still an ongoing research topic, so no method is widely adopted yet. Many methods don’t require full compliance with all REST constraints, the most neglected one being the hypermedia constraint. Web APIs
are therefore temporarily treated synonymously to HTTP APIs
here, as opposed to the term hypermedia APIs
, which signals actual hypermedia-driven REST APIs.
The Web Application Description Language (WADL) [16] can be considered the native HTTP equivalent of the messaging-driven WSDL. It can describe resources and the links between them, albeit in a way that tends to be more RPC-oriented. Its serialization format is an XML document that details resource types and their methods syntactically, without offering any form of functionality.
Several methods extend existing documents with annotations in order to capture extra semantics. MicroWSMO [17], built on top of the HTML-based format hRESTS [18], uses microformats to add machine-interpretable information to human-readable documentation. Yet, these annotations don’t describe a functional relation. MicroWSMO also offers lifting and lowering, the transformation of representation formats, whereas RESTdesc assumes this is handled by the server or another intermediary. Semantic Annotations for WSDL (SAWSDL) [19] offer comparable functionality, but extend WSDL instead. It offers functionality in the form of preconditions and effects. The Minimal Service Model [20] approaches Web service and Web API description in an operation-based manner, aiming to capture functional aspects in addition to parameters and methods.
The realization that the expressivity of RDF is too limited to directly express dynamic processes has inspired several methods based on other expression languages. The common denominator is the necessity for variables and quantification, which are easily represented in SPARQL-like graph patterns. Linked Open Services [21] and Linked Data Services [22] are two such approaches. As in OWL-S, graph patterns are expressed as literals, making the interpretation of descriptions non-integrated.
RESTdesc differs from the above approaches in its focus on hypermedia APIs and a direct level of description without the use of service elements such as parameters. It offers succinct descriptions that allow the discovery of Web APIs based on desired functionality. Furthermore, it has a built-in composition mechanism, which is the subject of the next chapter.
People browsing hypermedia applications know how to proceed after every page by relying on expectations and natural language, which is impossible for machine clients. RESTdesc descriptions therefore help machines look beyond the hypermedia controls offered in a single step by providing expectations of what can happen. Descriptions are instantiated into a plan to achieve a specific goal, given certain background knowledge. The interaction itself is guided by the plan, but remains driven by hypermedia: after each step, an agent reacts to a hypermedia response by interpreting it and replanning accordingly.
References
- [1]
- Fielding, R.T. (2000), Architectural Styles and the Design of Network-Based Software Architectures, PhD thesis, University of California, available at: http://www.ics.uci.edu/~fielding/
pubs/ .dissertation/ top.htm - [2]
- Fielding, R.T., Gettys, J., Mogul, J., Frystyk, H., Masinter, L., Leach, P. and Berners-Lee, T. (1999), Hypertext Transfer Protocol (HTTP), Request For Comments No. 2616, Internet Engineering Task Force, available at: http://tools.ietf.org/
html/ .rfc2616 - [3]
- Amundsen, M. (2011), Hypermedia APIs with HTML5 and Node, O’Reilly, available at: http://shop.oreilly.com/
product/ .0636920020530.do - [4]
- Koch, J., Velasco, C.A. and Ackermann, P. (2011), HTTP Vocabulary in RDF 1.0, Working Draft, World Wide Web Consortium, available at: http://www.w3.org/
TR/ .HTTP-in-RDF10/ - [5]
- Verborgh, R., Steiner, T., Van Deursen, D., Coppens, S., Gabarró Vallés, J. and Van de Walle, R. (2012), “Functional Descriptions as the Bridge between Hypermedia APIs and the Semantic Web”, in Proceedings of the Third International Workshop on RESTful Design, ACM, pp. 33–40, available at: http://ws-rest.org/
2012/ .proc/ a5-9-verborgh.pdf - [6]
- Verborgh, R., Steiner, T., Van Deursen, D., De Roo, J., Van de Walle, R. and Gabarró Vallés, J. (2013), “Capturing the functionality of Web services with functional descriptions”, Multimedia Tools and Applications, Springer, Vol. 64 No. 2, pp. 365–387, available at: https://doi.org/
10.1007/ .s11042-012-1004-5 - [7]
- Berners-Lee, T. and Connolly, D. (2011), Notation3 (N3): A Readable RDF Syntax, Team Submission, World Wide Web Consortium, available at: http://www.w3.org/
TeamSubmission/ .n3/ - [8]
- Gudgin, M., Hadley, M., Mendelsohn, N., Moreau, J.-J., Nielsen, H.F., Karmarkar, A. and Lafon, Y. (2007), SOAP Version 1.2 Part 1: Messaging Framework, Recommendation, World Wide Web Consortium, available at: http://www.w3.org/
TR/ .soap12-part1/ - [9]
- Booth, D. and Liu, C.K. (2007), Web Services Description Language (WSDL) Version 2.0 Part 0: Primer, Recommendation, World Wide Web Consortium, available at: http://www.w3.org/
TR/ .wsdl20-primer/ - [10]
- Lara, R., Roman, D., Polleres, A. and Fensel, D. (2004), “A Conceptual Comparison of WSMO and OWL-S”, in Zhang, L.-J. and Jeckle, M. (Eds.), Web Services, Vol. 3250, Lecture Notes in Computer Science, Springer, pp. 254–269.
- [11]
- Berners-Lee, T., Hendler, J. and Lassila, O. (2001), “The Semantic Web”, Scientific American, Vol. 284 No. 5, pp. 34–43, available at: http://www.scientificamerican.com/
article.cfm?id=the-semantic-web . - [12]
- Martin, D., Burstein, M., McDermott, D., McIlraith, S., Paolucci, M., Sycara, K., McGuinness, D.L., et al. (2007), “Bringing Semantics to Web Services with OWL-S”, World Wide Web, Kluwer Academic Publishers, Vol. 10 No. 3, pp. 243–277, available at: https://doi.org/
10.1007/ .s11280-007-0033-x - [13]
- Verborgh, R., Van Deursen, D., De Roo, J., Mannens, E. and Van de Walle, R. (2010), “SPARQL Endpoints as Front-end for Multimedia Processing Algorithms”, in Proceedings of the 4th Workshop on Service Matchmaking and Resource Retrieval in the Semantic Web, available at: http://ceur-ws.org/
Vol-667/ .smr22010_submission_4.pdf - [14]
- Verborgh, R., Van Deursen, D., Mannens, E., Poppe, C. and Van de Walle, R. (2012), “Enabling context-aware multimedia annotation by a novel generic semantic problem-solving platform”, Multimedia Tools and Applications, Springer, Vol. 61 No. 1, pp. 105–129, available at: https://doi.org/
10.1007/ .s11042-010-0709-6 - [15]
- Verborgh, R., Harth, A., Maleshkova, M., Stadtmüller, S., Steiner, T., Taheriyan, M. and Van de Walle, R. (2014), “Survey of Semantic Description of REST APIs”, in Pautasso, C., Wilde, E. and Alarcón, R. (Eds.), REST: Advanced Research Topics and Practical Applications, pp. 69–89, available at: http://link.springer.com/
chapter/ .10.1007/ 978-1-4614-9299-3_5 - [16]
- Hadley, M. (2009), Web Application Description Language, Member Submission, World Wide Web Consortium, available at: http://www.w3.org/
Submission/ .wadl/ - [17]
- Kopecký, J., Vitvar, T. and Fensel, D. (2009), MicroWSMO and hRESTS, No. D3.4.3, SOA4All, available at: http://sweet.kmi.open.ac.uk/
pub/ .microWSMO.pdf - [18]
- Kopecký, J., Gomadam, K. and Vitvar, T. (2008), “hRESTS: An HTML Microformat for Describing RESTful Web Services”, in Proceedings of the 2008 IEEE/
WIC/ , IEEE Computer Society, pp. 619–625, available at: https://doi.org/ACM International Conference on Web Intelligence and Intelligent Agent Technology 10.1109/ .WIIAT.2008.379 - [19]
- Kopecký, J., Vitvar, T., Bournez, C. and Farrell, J. (2007), “SAWSDL: Semantic Annotations for WSDL and XML Schema”, Internet Computing, IEEE, Vol. 11 No. 6, pp. 60–67, available at: https://doi.org/
10.1109/ .MIC.2007.134 - [20]
- Pedrinaci, C., Liu, D., Maleshkova, M., Lambert, D., Kopecký, J. and Domingue, J. (2010), “iServe: a Linked Services Publishing Platform”, in Proceedings of the Ontology Repositories and Editors for the Semantic Web Workshop, available at: http://ceur-ws.org/
Vol-596/ .paper-10.pdf - [21]
- Krummenacher, R., Norton, B. and Marte, A. (2010), “Towards Linked Open Services and Processes”, in Future Internet Symposium, Vol. 6369, Lecture Notes in Computer Science, Springer, pp. 68–77, available at: https://doi.org/
10.1007/ .978-3-642-15877-3_8 - [22]
- Speiser, S. and Harth, A. (2011), “Integrating Linked Data and Services with Linked Data Services”, in The Semantic Web: Research and Applications, Vol. 6643, Lecture Notes in Computer Science, Springer, pp. 170–184, available at: https://doi.org/
10.1007/ .978-3-642-21034-1_12